
Nanbeige 4.2 3B Architecture
Back to Nanbeige 4.2 3B in the gallery
BOSS Zhipin
Compact agentic model that runs the same 22-layer dense transformer stack twice, resulting in 44 transformer blocks (layers) without duplicating the layer weights.
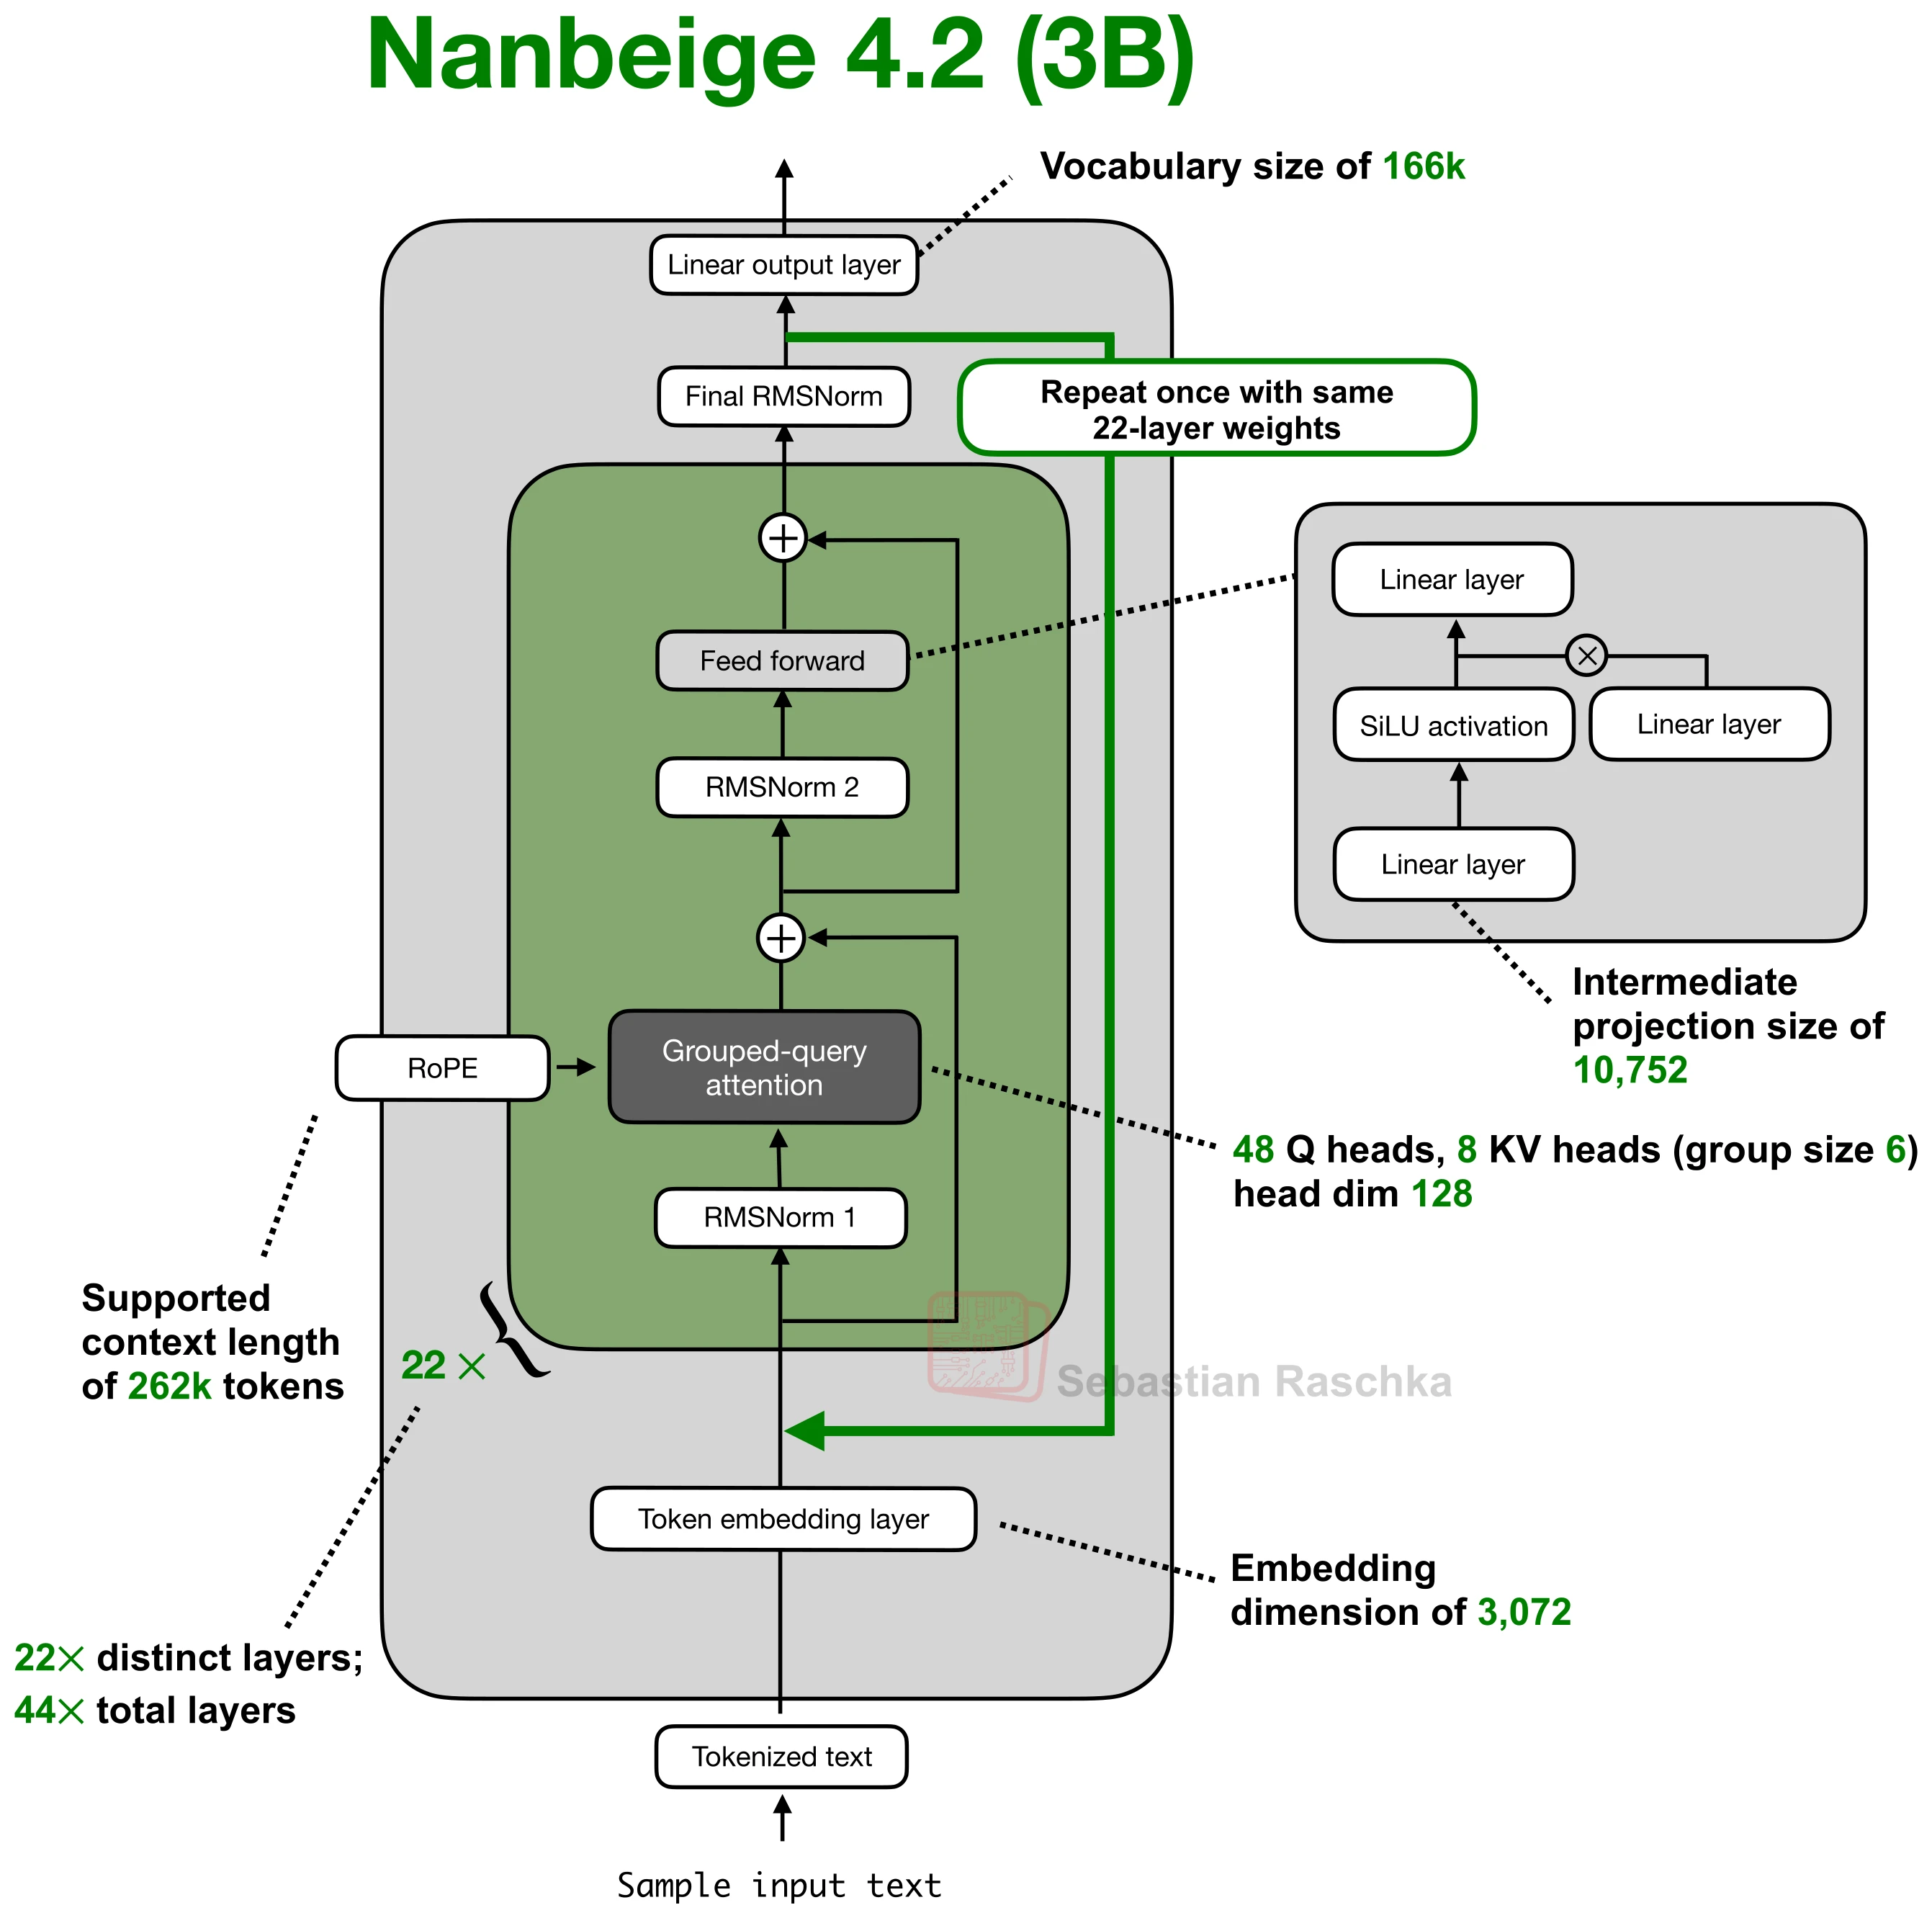
Architecture and specifications
- Scale
- 4B total, 3B non-embedding
- Context (tokens)
- 262,144
- Vocabulary
- 166,144 (~166k)
- License
- Apache License 2.0
- Date
- 2026-07-21
- Decoder type
- Dense
- Attention
- GQA with RoPE
- Layer mix
- 22 shared GQA layers × 2 passes
- KV cache / token (bf16) info
- 176 KiB · High
- Key detail
- Reuses the same 22-layer stack for a second pass, giving 44 block applications with 3B non-embedding parameters.
Training and benchmarks
- Pretraining data
- 28T tokens The new looped architecture was pretrained from scratch on 28T tokens. Nanbeige 4.2 technical report
- Post-training methods
- SFT, RLHF, RLVR Three-stage SFT, two-stage RLHF, reasoning RL with correctness and length rewards, and agentic RL using executable task checks and action rubrics. Nanbeige 4.2 technical report