
Inkling 2 Mini Architecture
Back to Inkling 2 Mini in the gallery
Thinking Machines Lab
Inkling 2 Mini runs its middle 12 layers three times with shared weights. The first and last six layers each run once, giving 48 layer applications per token from 24 distinct layers.
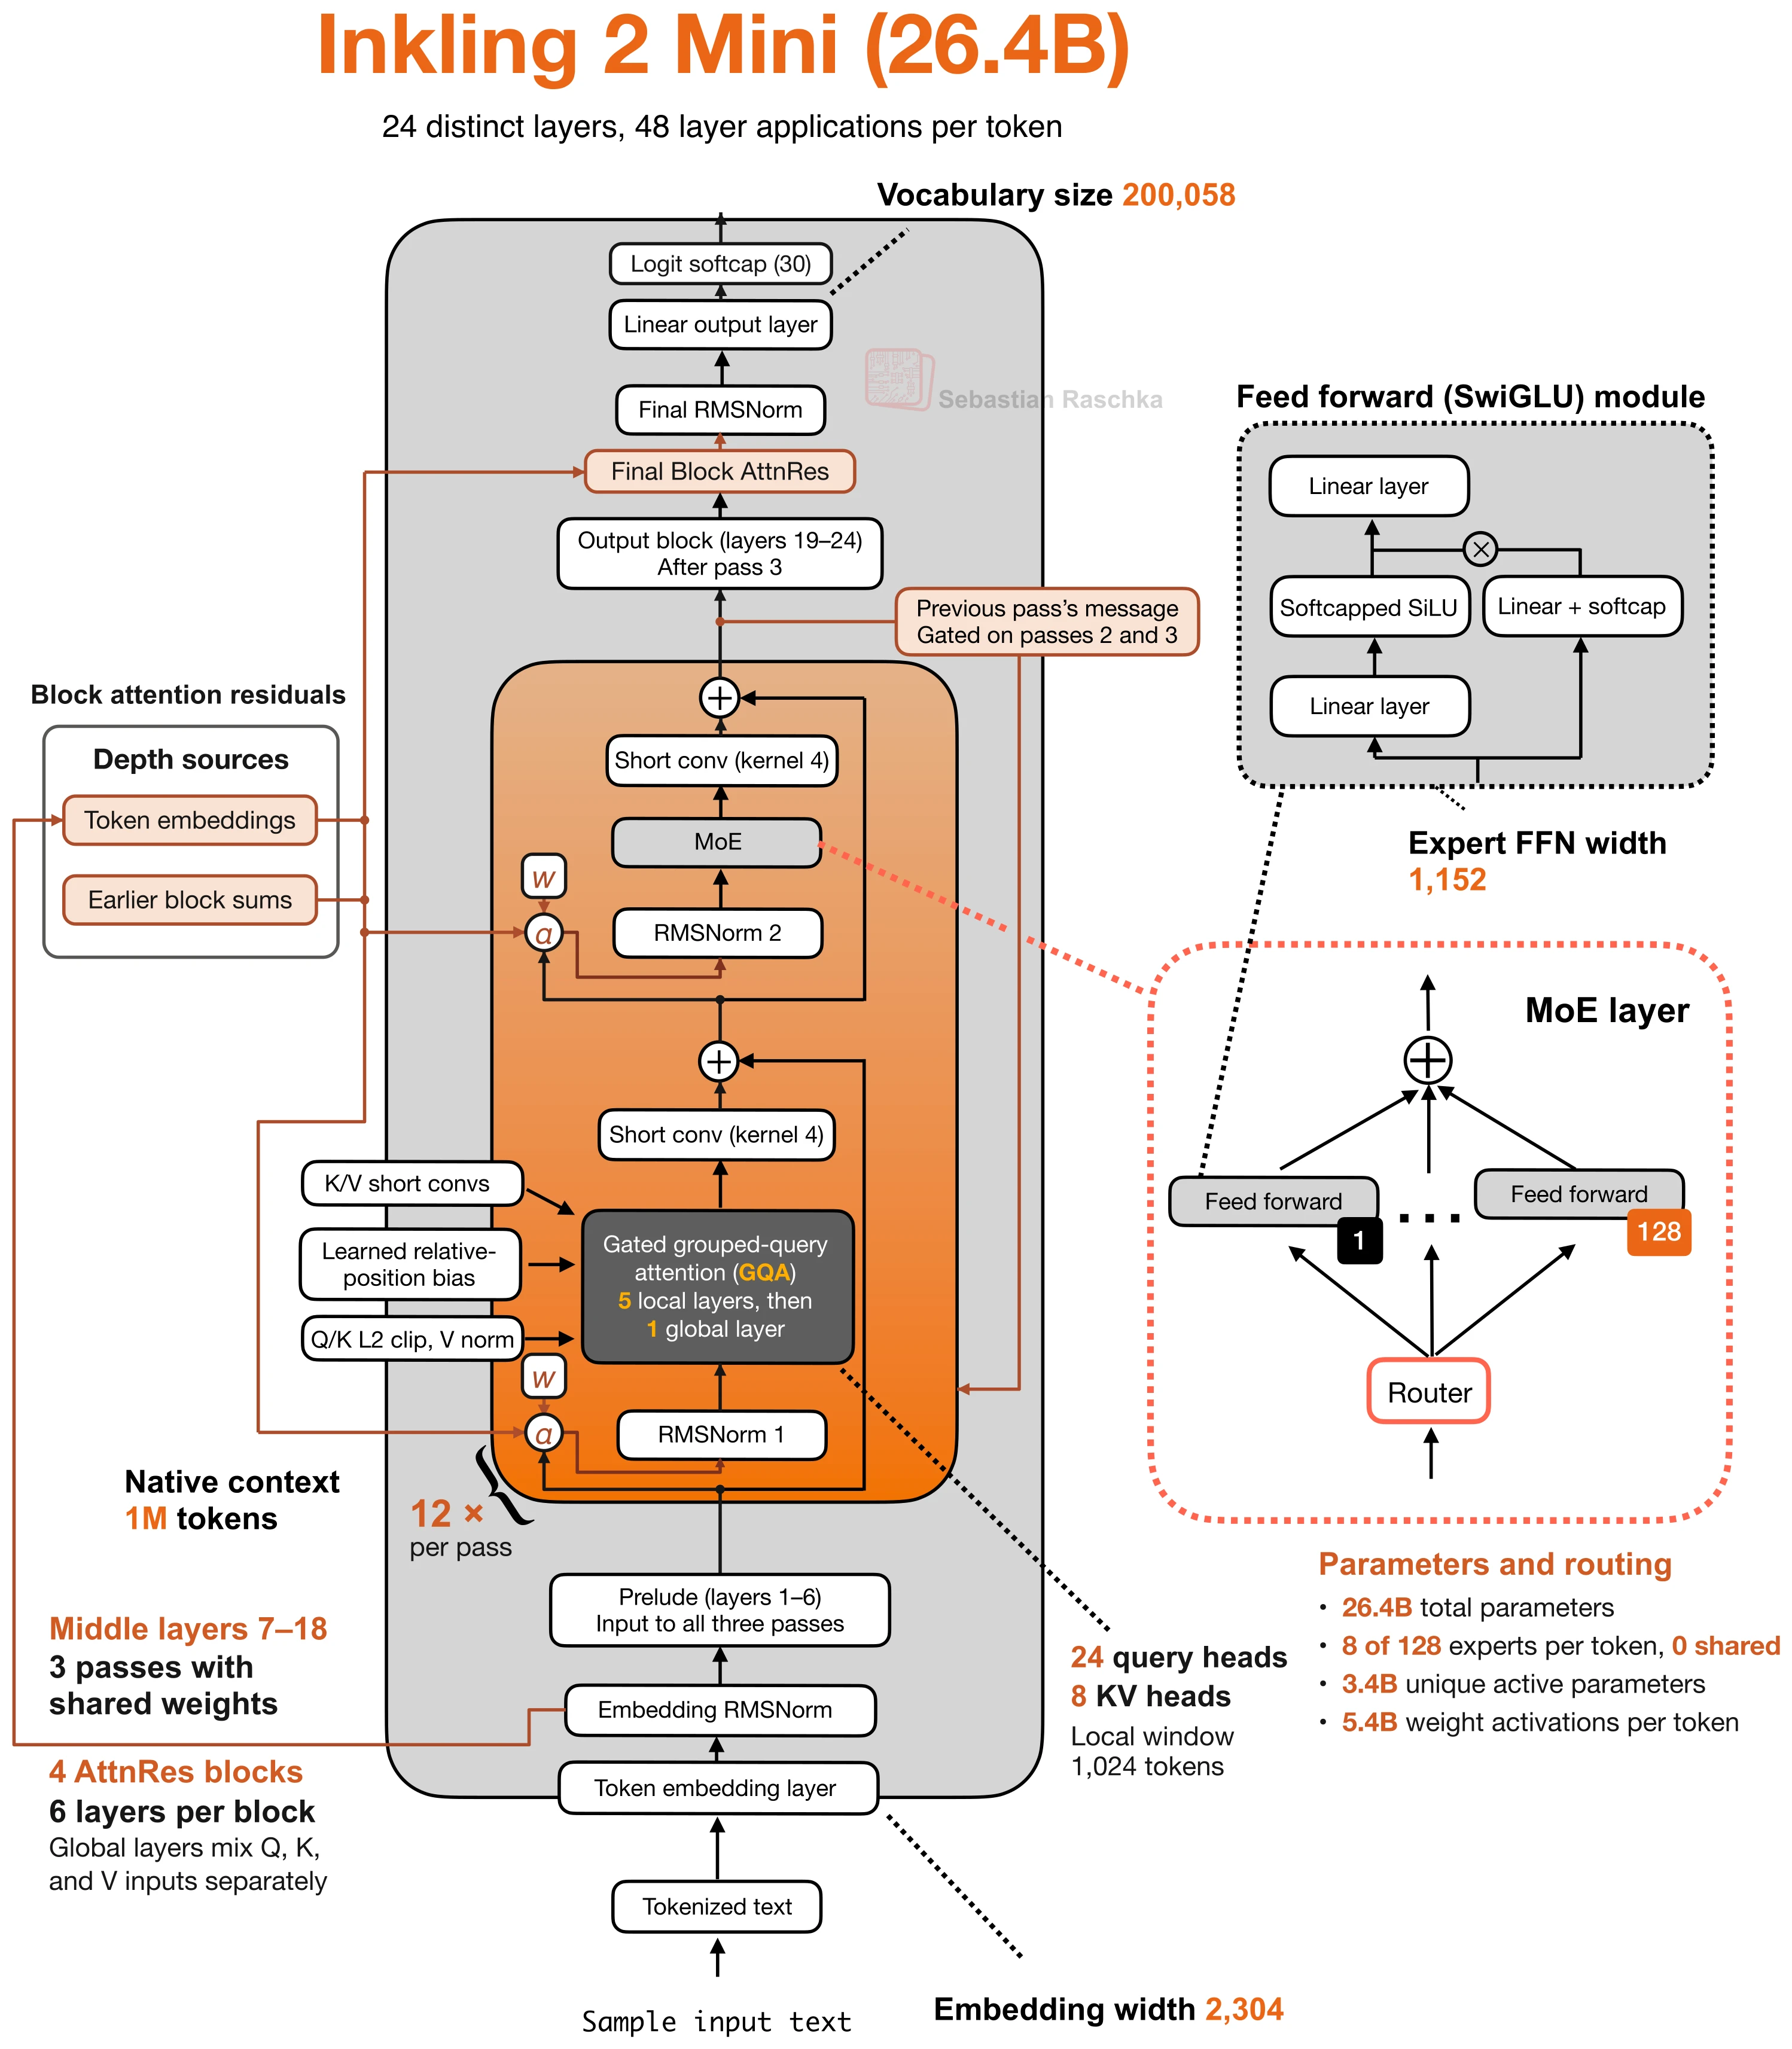
Architecture and specifications
- Scale
- 26.4B total, 3.4B unique active (12.9% active), 5.4B weight activations per token
- Context (tokens)
- 1,048,576
- Vocabulary
- 200,058 (padded to 201,024)
- License
- Apache License 2.0
- Date
- 2026-11-20
- Decoder type
- Sparse MoE
- Attention
- Gated GQA with learned relative-position bias, 24 query heads, and 8 KV heads
- Layer mix
- 5 sliding-window (1,024 tokens) + 1 global GQA per block
- KV cache / token (bf16) info
- 192 KiB · High
- Key detail
- Each pass starts from the same six-layer prelude. Passes two and three also receive a gated message from the previous pass. Each MoE layer selects 8 of 128 experts per token.
Training and benchmarks
- Pretraining data
- 1T tokens after expert pruning During mid-training, each layer went from 384 experts to 128. The remaining experts trained on 1T tokens distilled from a larger Inkling model. The full pretraining token count is undisclosed. Pruning and healing
- Post-training methods
- SFT, RL, Distillation Supervised fine-tuning was followed by 2.2T tokens of RL over 2,000 steps. The team also used on-policy distillation for alignment. Training overview