
Qwen3 0.6B Architecture
Back to Qwen3 0.6B in the gallery
Alibaba Cloud
Tiny current-generation Qwen model that trades width for more depth and a low memory footprint.
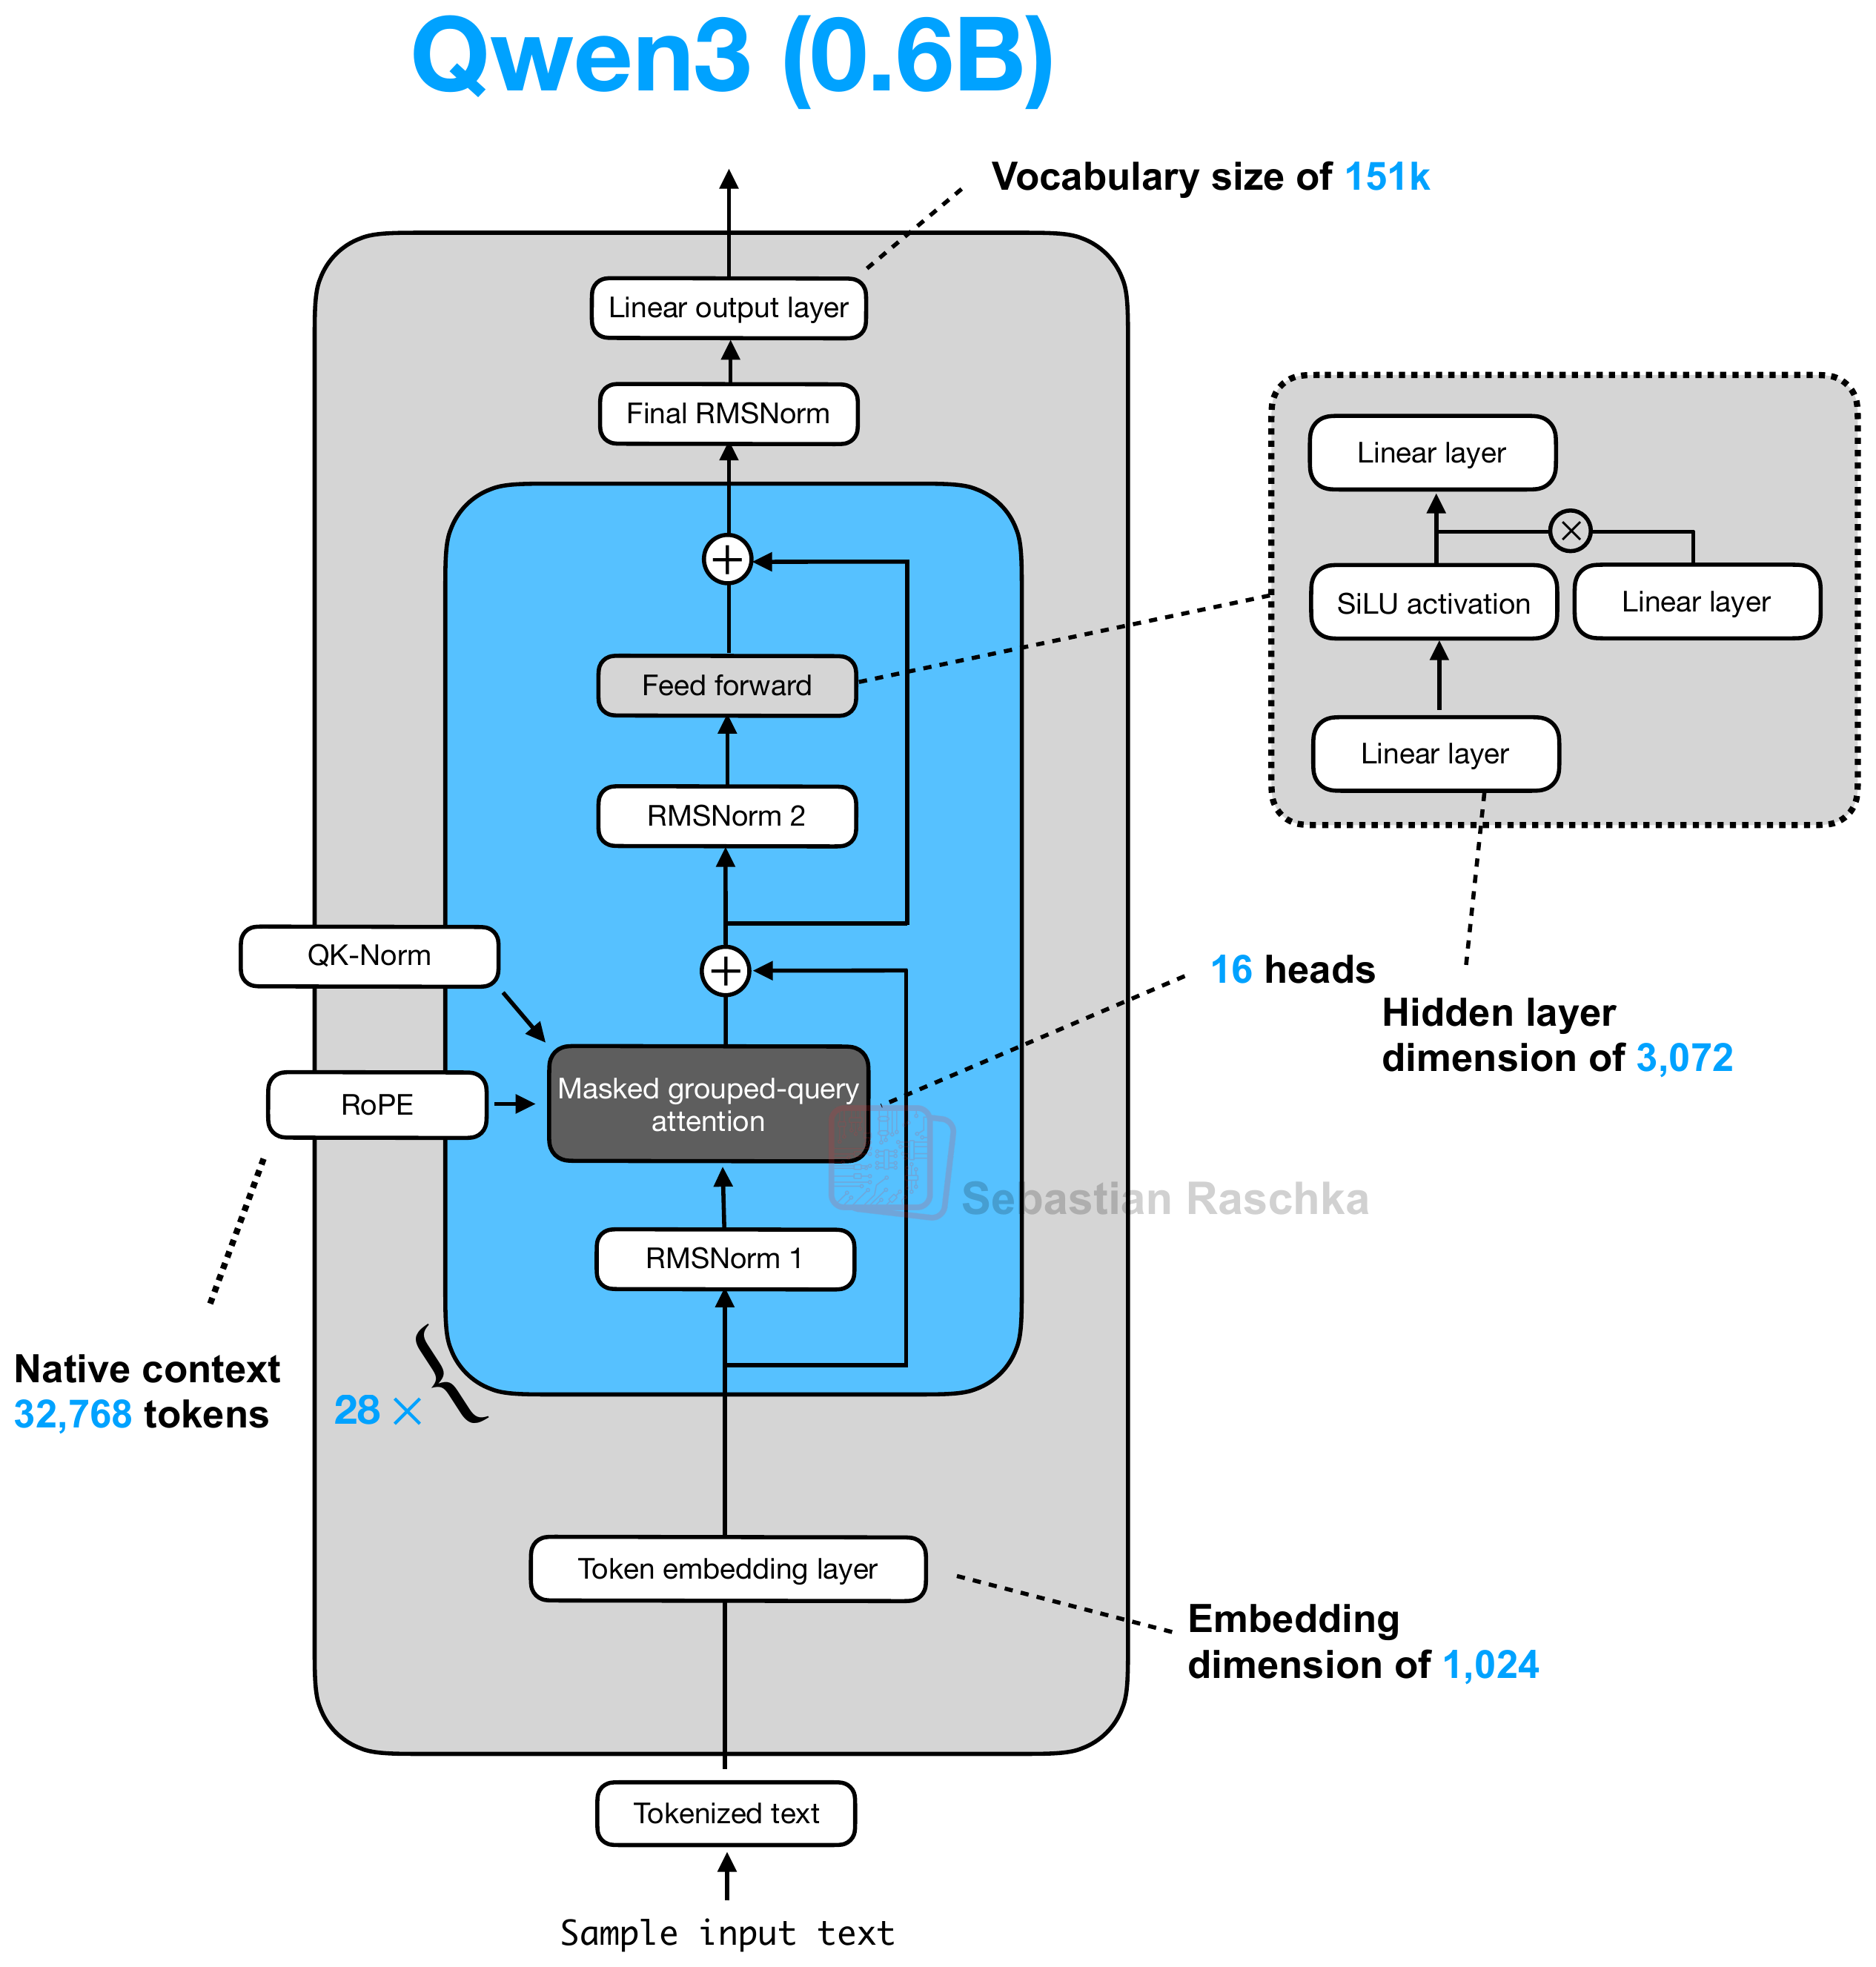
Architecture and specifications
- Scale
- 0.6B parameters
- Context (tokens)
- 32,768
- License
- Apache License 2.0
- Date
- 2025-04-28
- Decoder type
- Dense
- Attention
- GQA
- Layer mix
- 28 GQA
- KV cache / token (bf16) info
- 112 KiB · Moderate
- Key detail
- Deeper than Llama 3.2 1B and unusually practical for local experiments and teaching.
Training and benchmarks
- Pretraining data
- ≈36T tokens Family pretraining budget; excludes post-training. Qwen3 technical report
- Post-training methods
- SFT, Distillation Instruction/reasoning counterpart uses response-supervised and on-policy teacher distillation. Base checkpoints have no post-training. Qwen3 technical report