
Olala v1.0 Mini 7A1B Architecture
Back to Olala v1.0 Mini 7A1B in the gallery
OVHai LLM (OVHcloud)
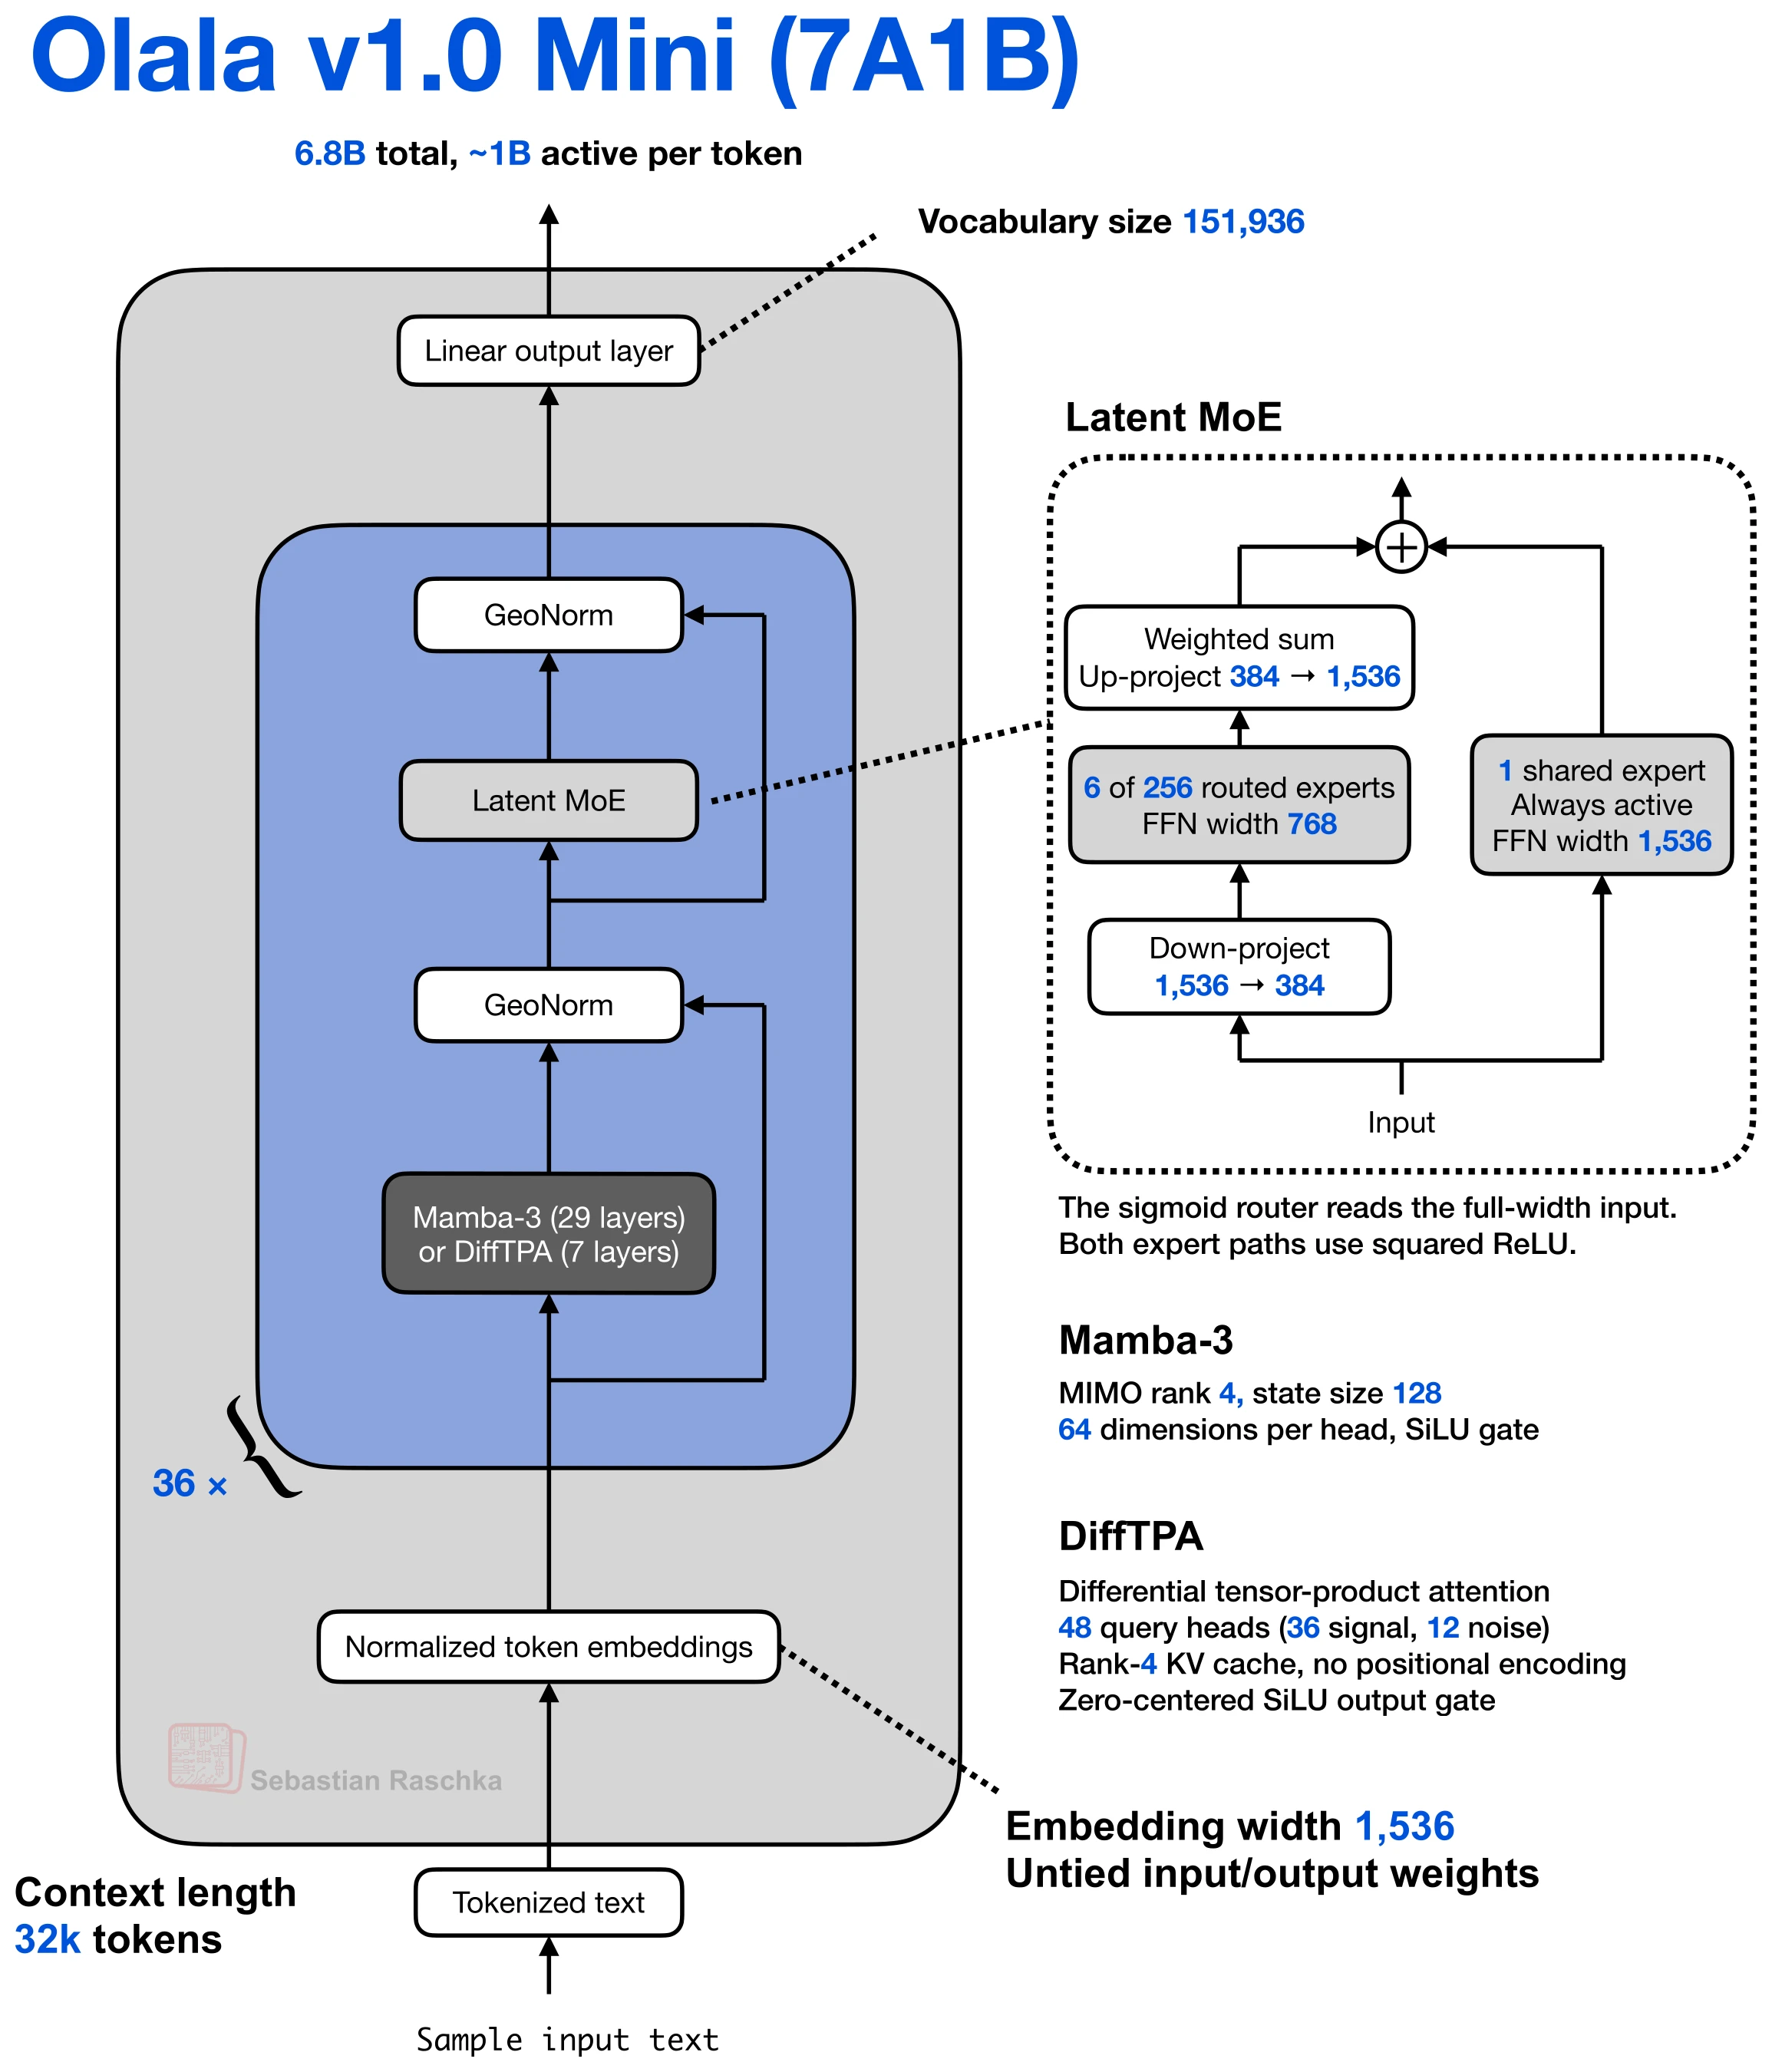
Olala v1.0 Mini 7A1B pairs 29 Mamba-3 layers with 7 differential tensor-product attention layers. Each of its 36 layers uses a latent MoE and GeoNorm residual connections.
Architecture and specifications
- Scale
- 6.8B total, ~1B active (~14.7% active)
- Context (tokens)
- 32,768
- Vocabulary
- 151,936
- License
- Apache License 2.0
- Date
- 2026-11-19
- Decoder type
- Hybrid MoE
- Attention
- Differential tensor-product attention (DiffTPA) with 36 signal heads, 12 noise heads, and a gated output
- Layer mix
- 29 Mamba-3 + 7 DiffTPA
- KV cache / token (bf16) info
- 15.3125 KiB (rank-4 factorized cache) · Very low
- Key detail
- The router selects 6 of 256 experts from the full 1,536-dimensional input. Those experts operate on 384 dimensions, while one shared expert processes the full input.
Training and benchmarks
- Pretraining data
- 12.8T tokens Main pretraining used 10.4T tokens of multilingual text, code, mathematics, and translations. Annealing added 2.38T tokens with more mathematics, code, and instruction data. Model card and training recipe
- Post-training methods
- SFT, RL Supervised fine-tuning used 36.9M samples (about 162B tokens). Four RL stages covered instruction following and math, code, assistant behavior, and tool use. Model card and training recipe