
Instella-MoE 16B-A3B Architecture
Back to Instella-MoE 16B-A3B in the gallery
AMD
Instella-MoE adds a sigmoid output gate to DeepSeek-style multi-head latent attention. After one dense layer, each of its 26 MoE layers uses two shared experts and six of 64 routed experts per token.
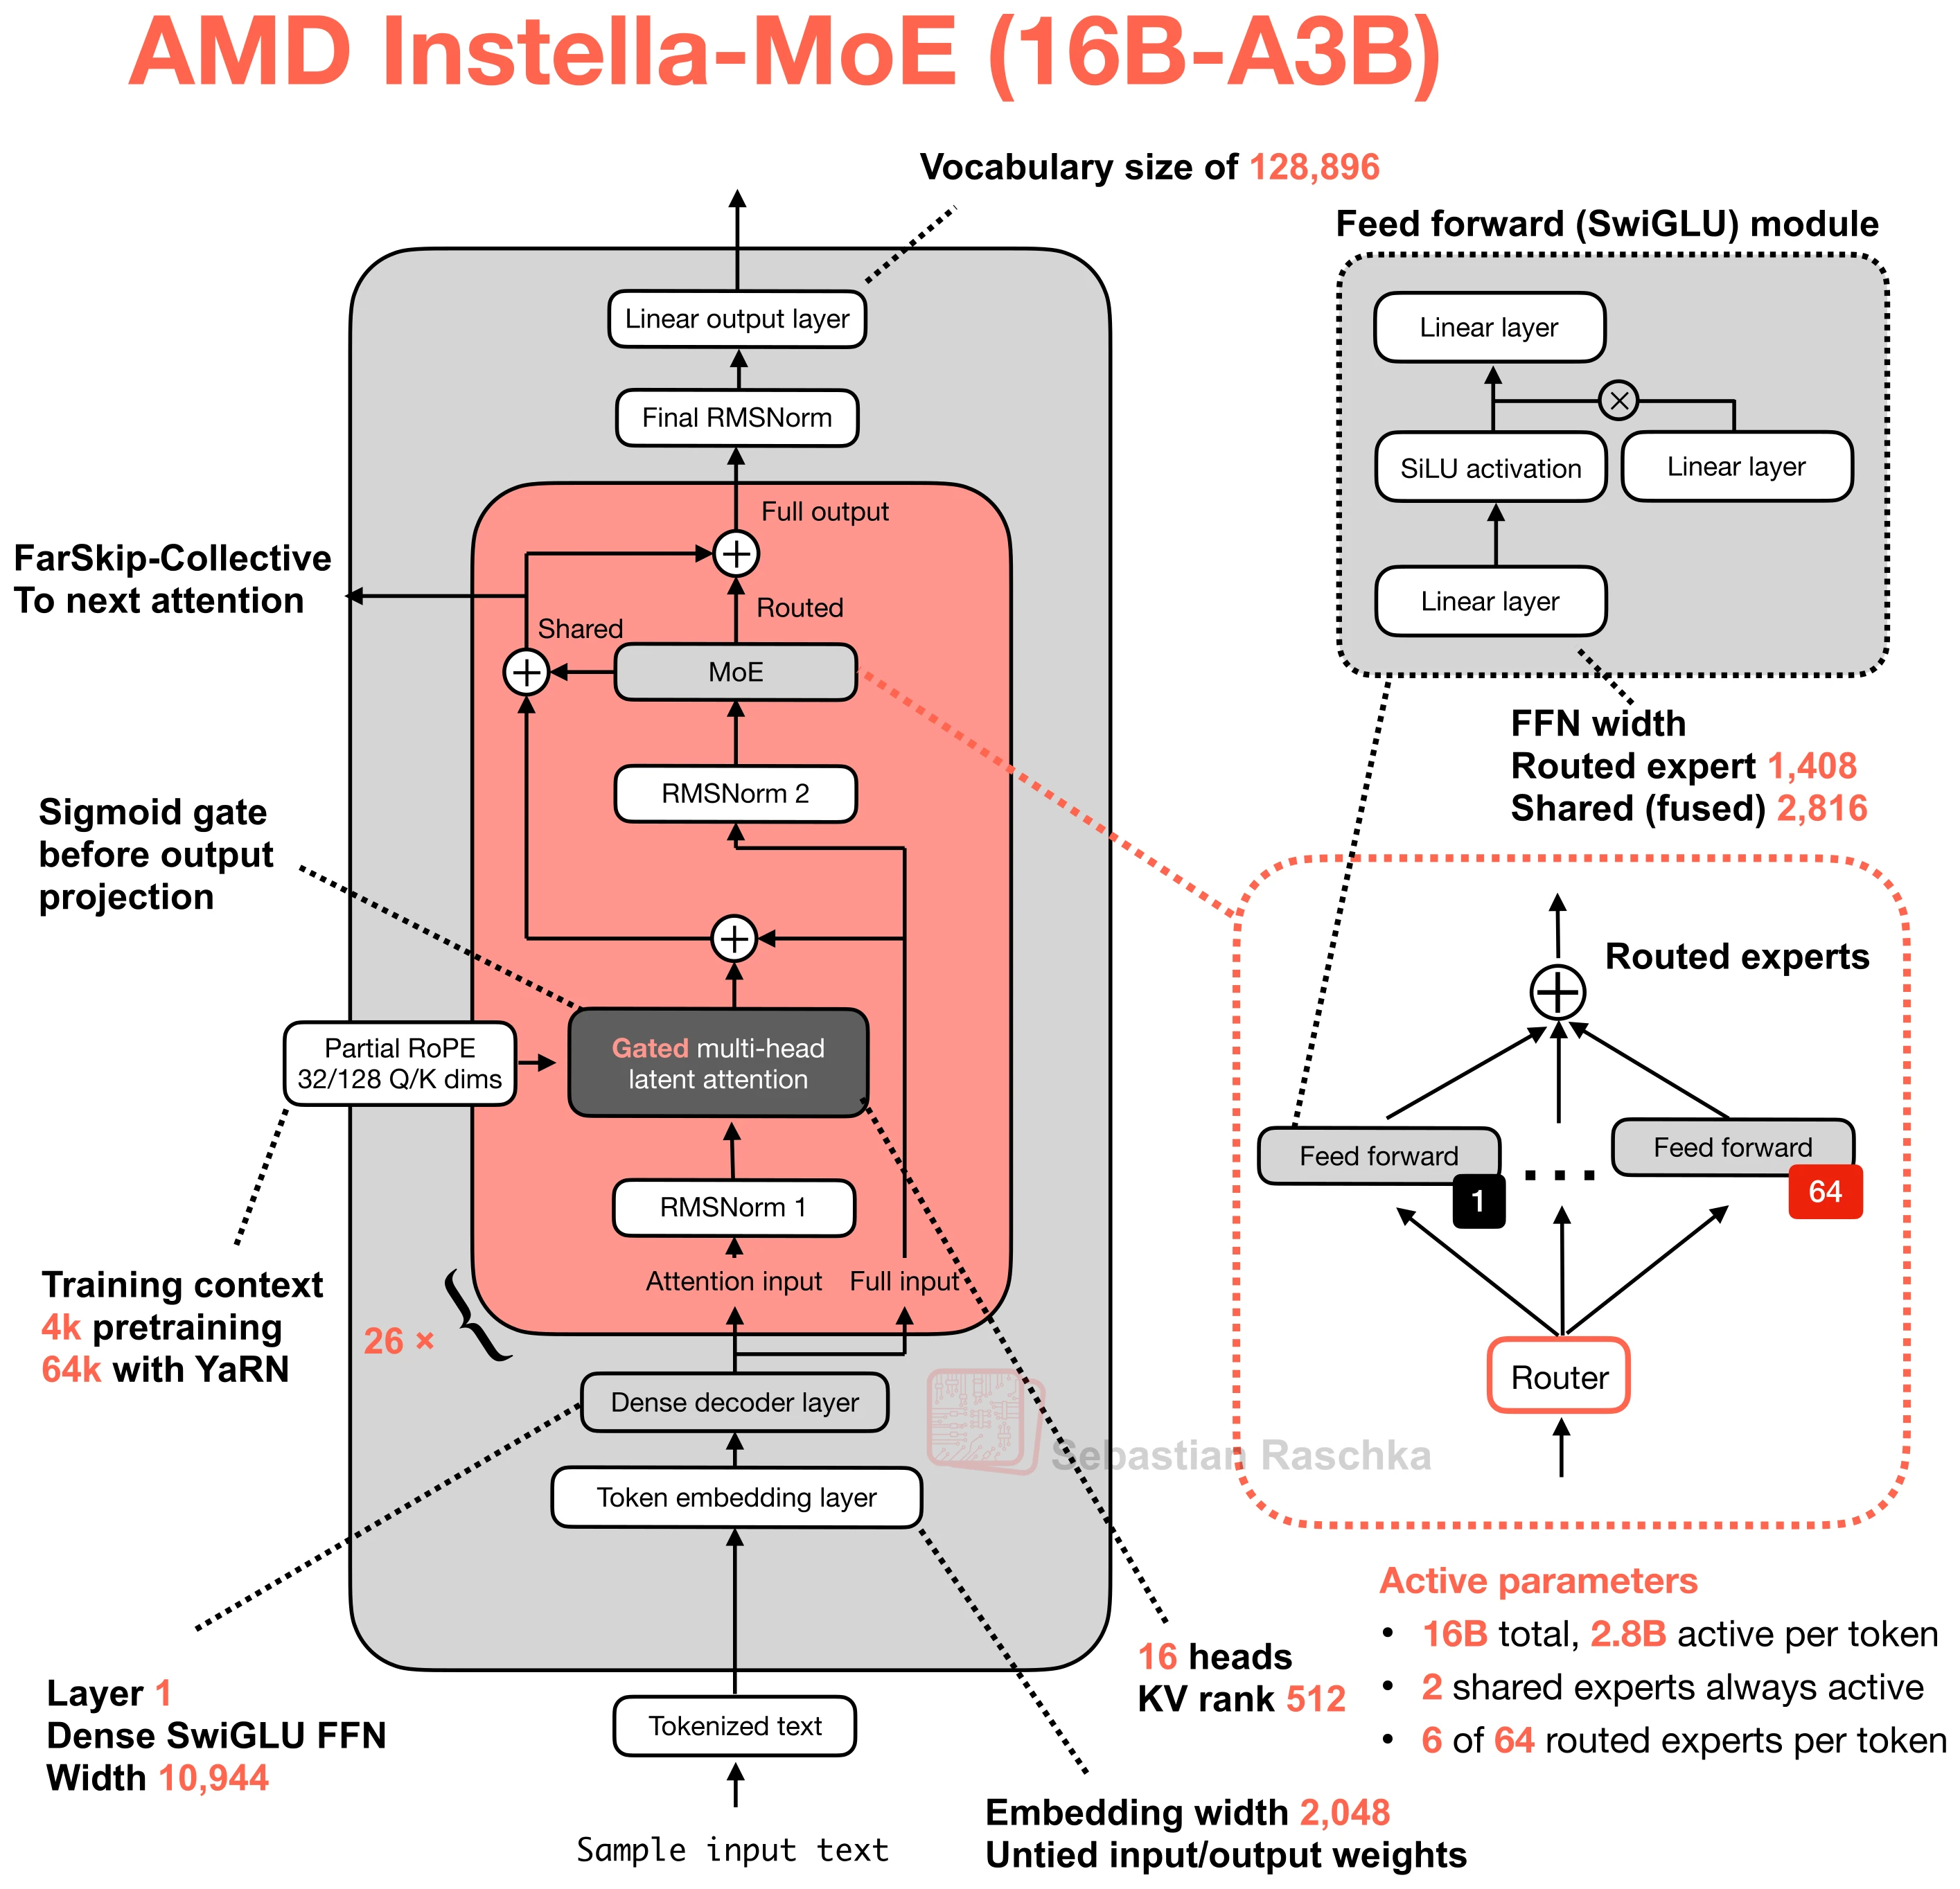
Architecture and specifications
- Scale
- 16B total, 2.8B active (17.5% active)
- Context (tokens)
- 65,536
- Vocabulary
- 128,896
- License
- Research-Only RAIL Model License
- Date
- 2026-07-24
- Decoder type
- Sparse MoE
- Attention
- Gated MLA with partial RoPE
- Layer mix
- 27 gated MLA (1 dense FFN + 26 MoE)
- KV cache / token (bf16) info
- 28.6875 KiB (compact MLA cache) · Low
- Key detail
- FarSkip-Collective feeds the full block input directly to the experts. The next layer can start attention once the attention and shared-expert outputs have been added to the residual, while the routed outputs are still being combined.
Training and benchmarks
- Pretraining data
- 7.1T tokens AMD pretrained on 4,096-token sequences, then mid-trained on about 100B tokens of STEM and reasoning data. A separate YaRN extension stage produced the Base checkpoint with a 65,536-token window. Instella-MoE technical report · AMD release announcement
- Post-training methods
- SFT, DPO, RLVR, Distillation AMD fine-tuned the Base model with SFT and DPO, then trained it with verifiable instruction-following rewards and on-policy distillation from multiple teachers. The final Think checkpoint config lists 32,768 positions. Instella-MoE technical report · Think checkpoint configuration