
Pre-Training Without Learning Rate Decay
This could be the start of a trend in new pre-training recipes: No learning rate (LR) decay phase anymore. (Also seen in Kolibri.)
Instead, use a constant LR plus averaging the last N checkpoints (or a running weight average).
I guess that makes it easier in practice because you don’t have to commit to a total training length upfront.
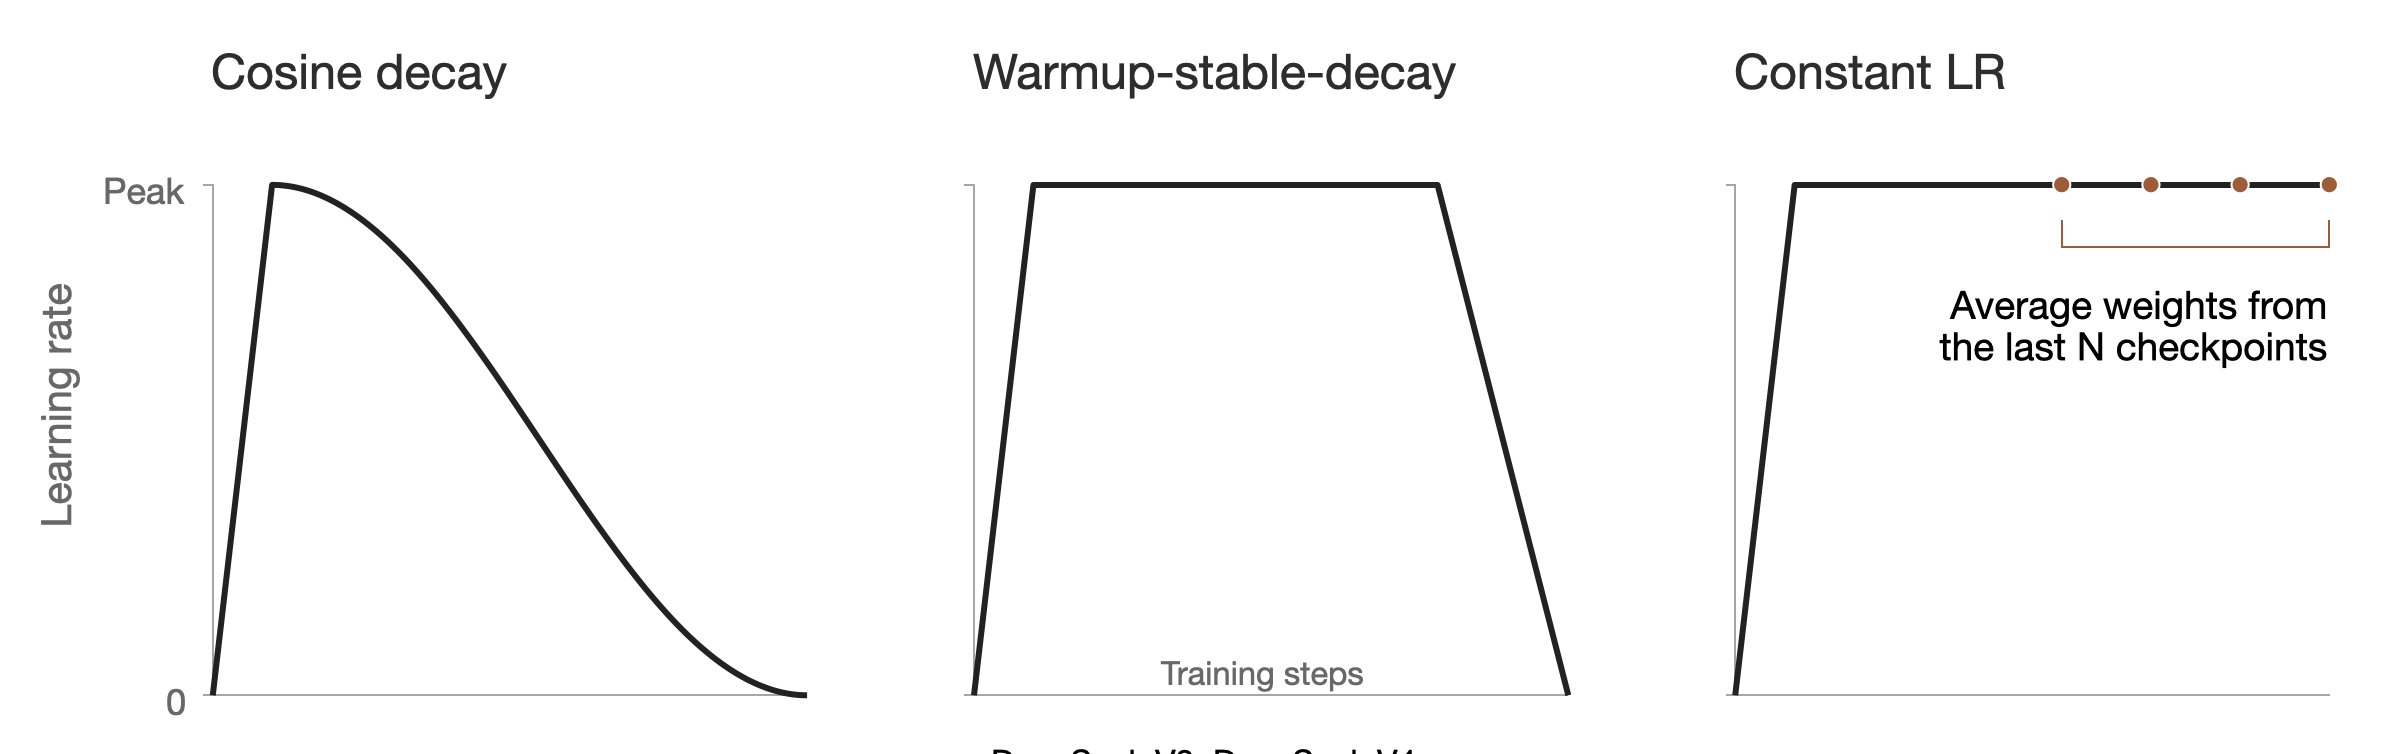
A little meta analysis based on those who share training details.
- Classic cosine decay: Llama 3, OLMo 2, OLMo 3, GLM-4.5, GLM-5, Kimi K3, Phi-4.
- WSD (“Warmup-Stable-Decay”): DeepSeek V3, DeepSeek V4, DeepSeek V4.1-Flash, Kimi K2, Kimi Linear, Nemotron 3 Nano, Nemotron 3 Super, SmolLM3, MiniMax M2.
- No decay (constant LR plus checkpoint averaging): Kolibri-1 (see architecture in the LLM gallery), DatologyAI’s models (see architecture in the LLM gallery).
Source: lightly edited website version of my X post, quoting DatologyAI’s note on weight averaging.
Read Next
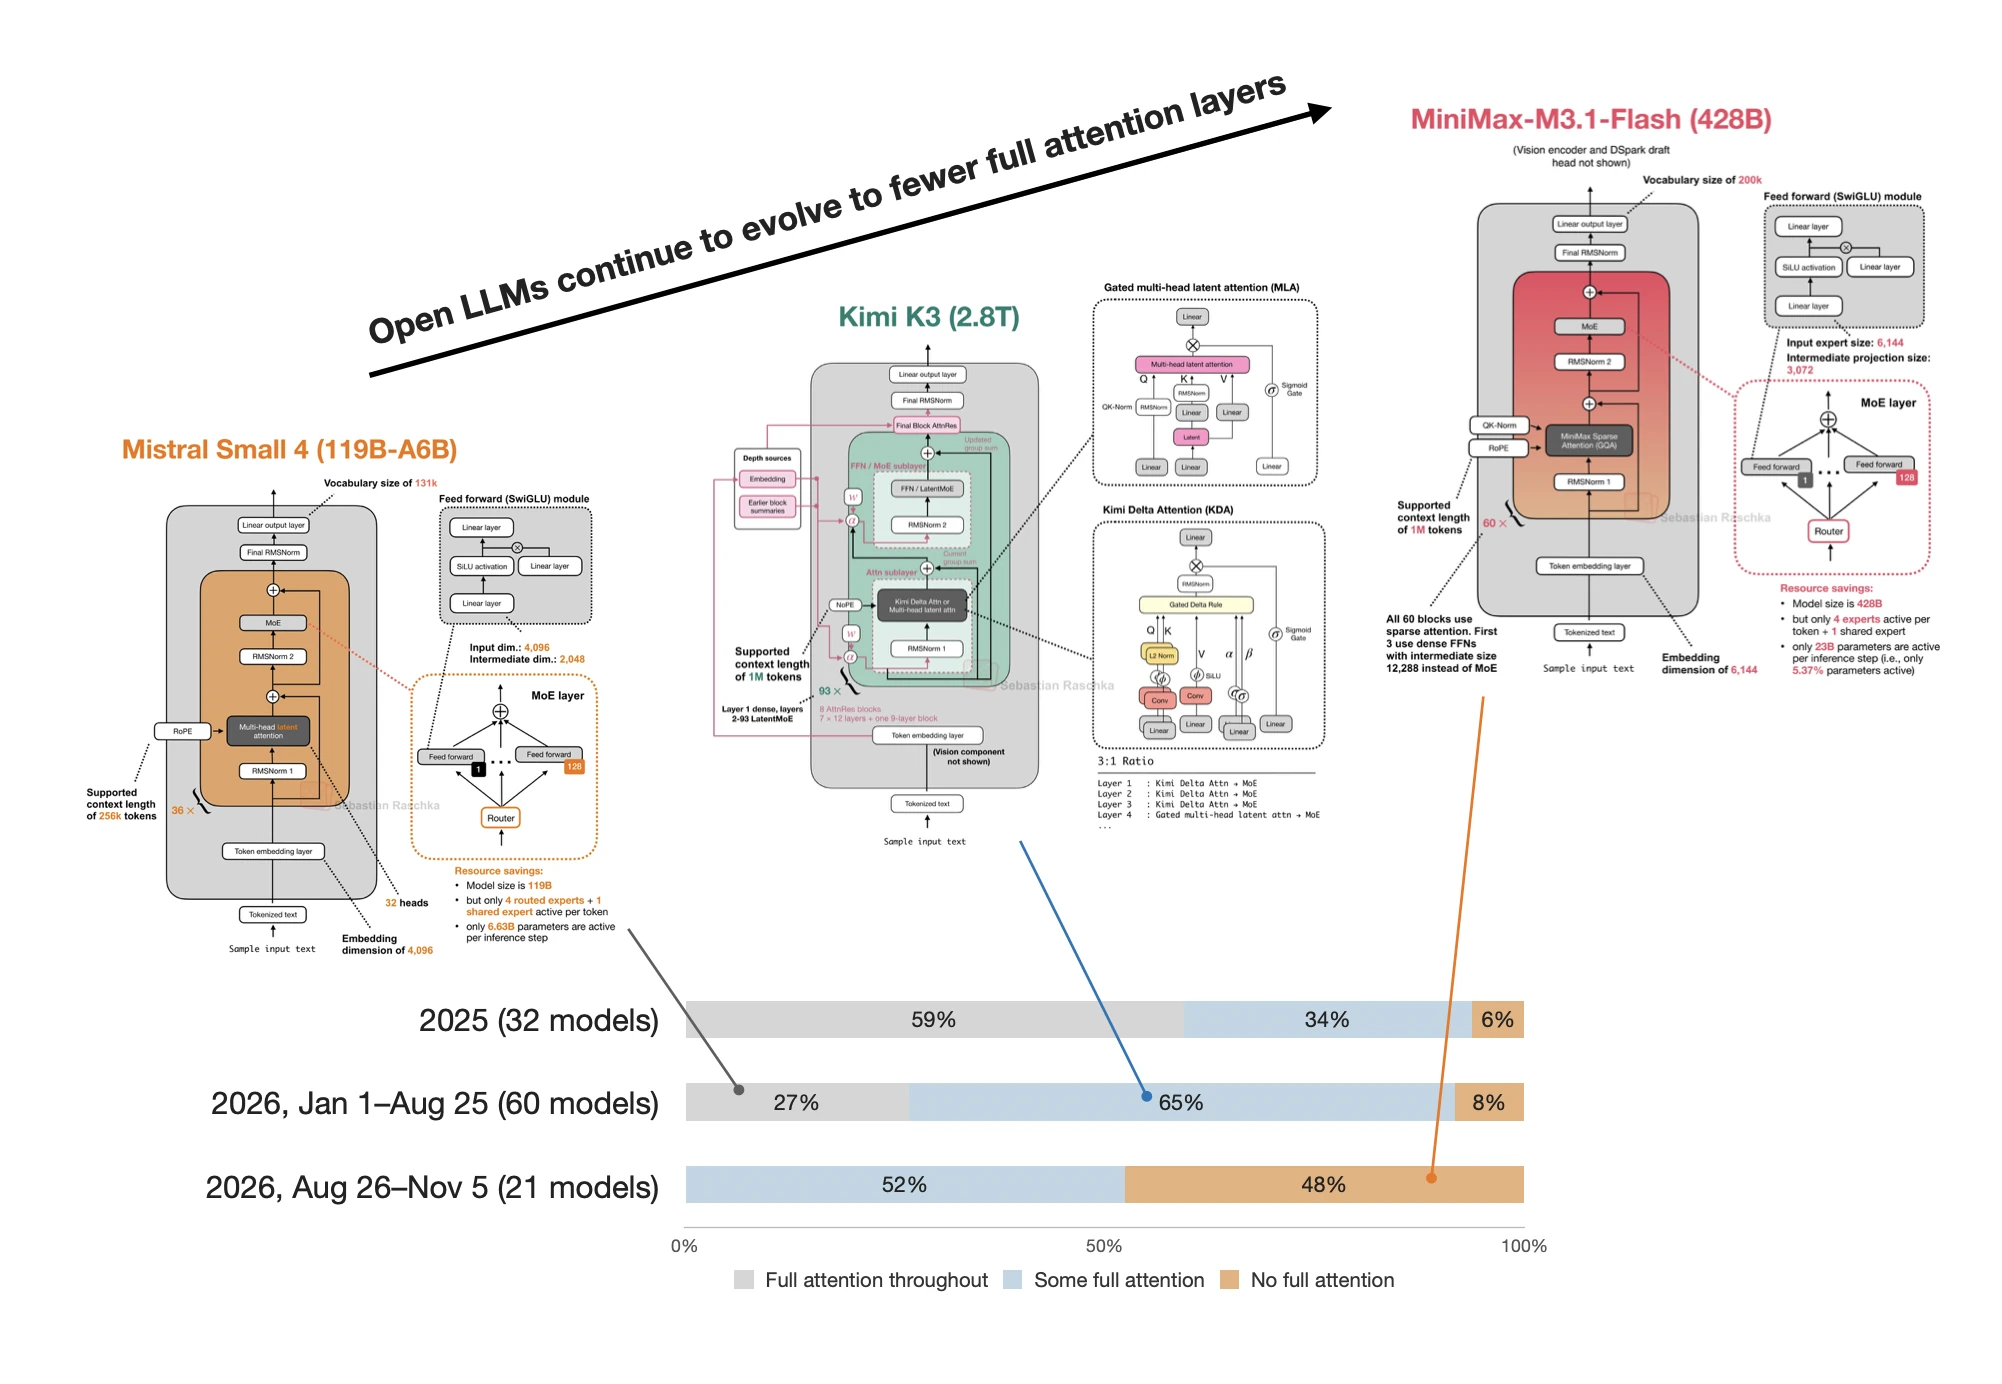 From Full to Hybrid Attention in LLMs
How open-weight LLMs are shifting from full attention to hybrid and sparse designs, and what that means for long-context compute and memory.
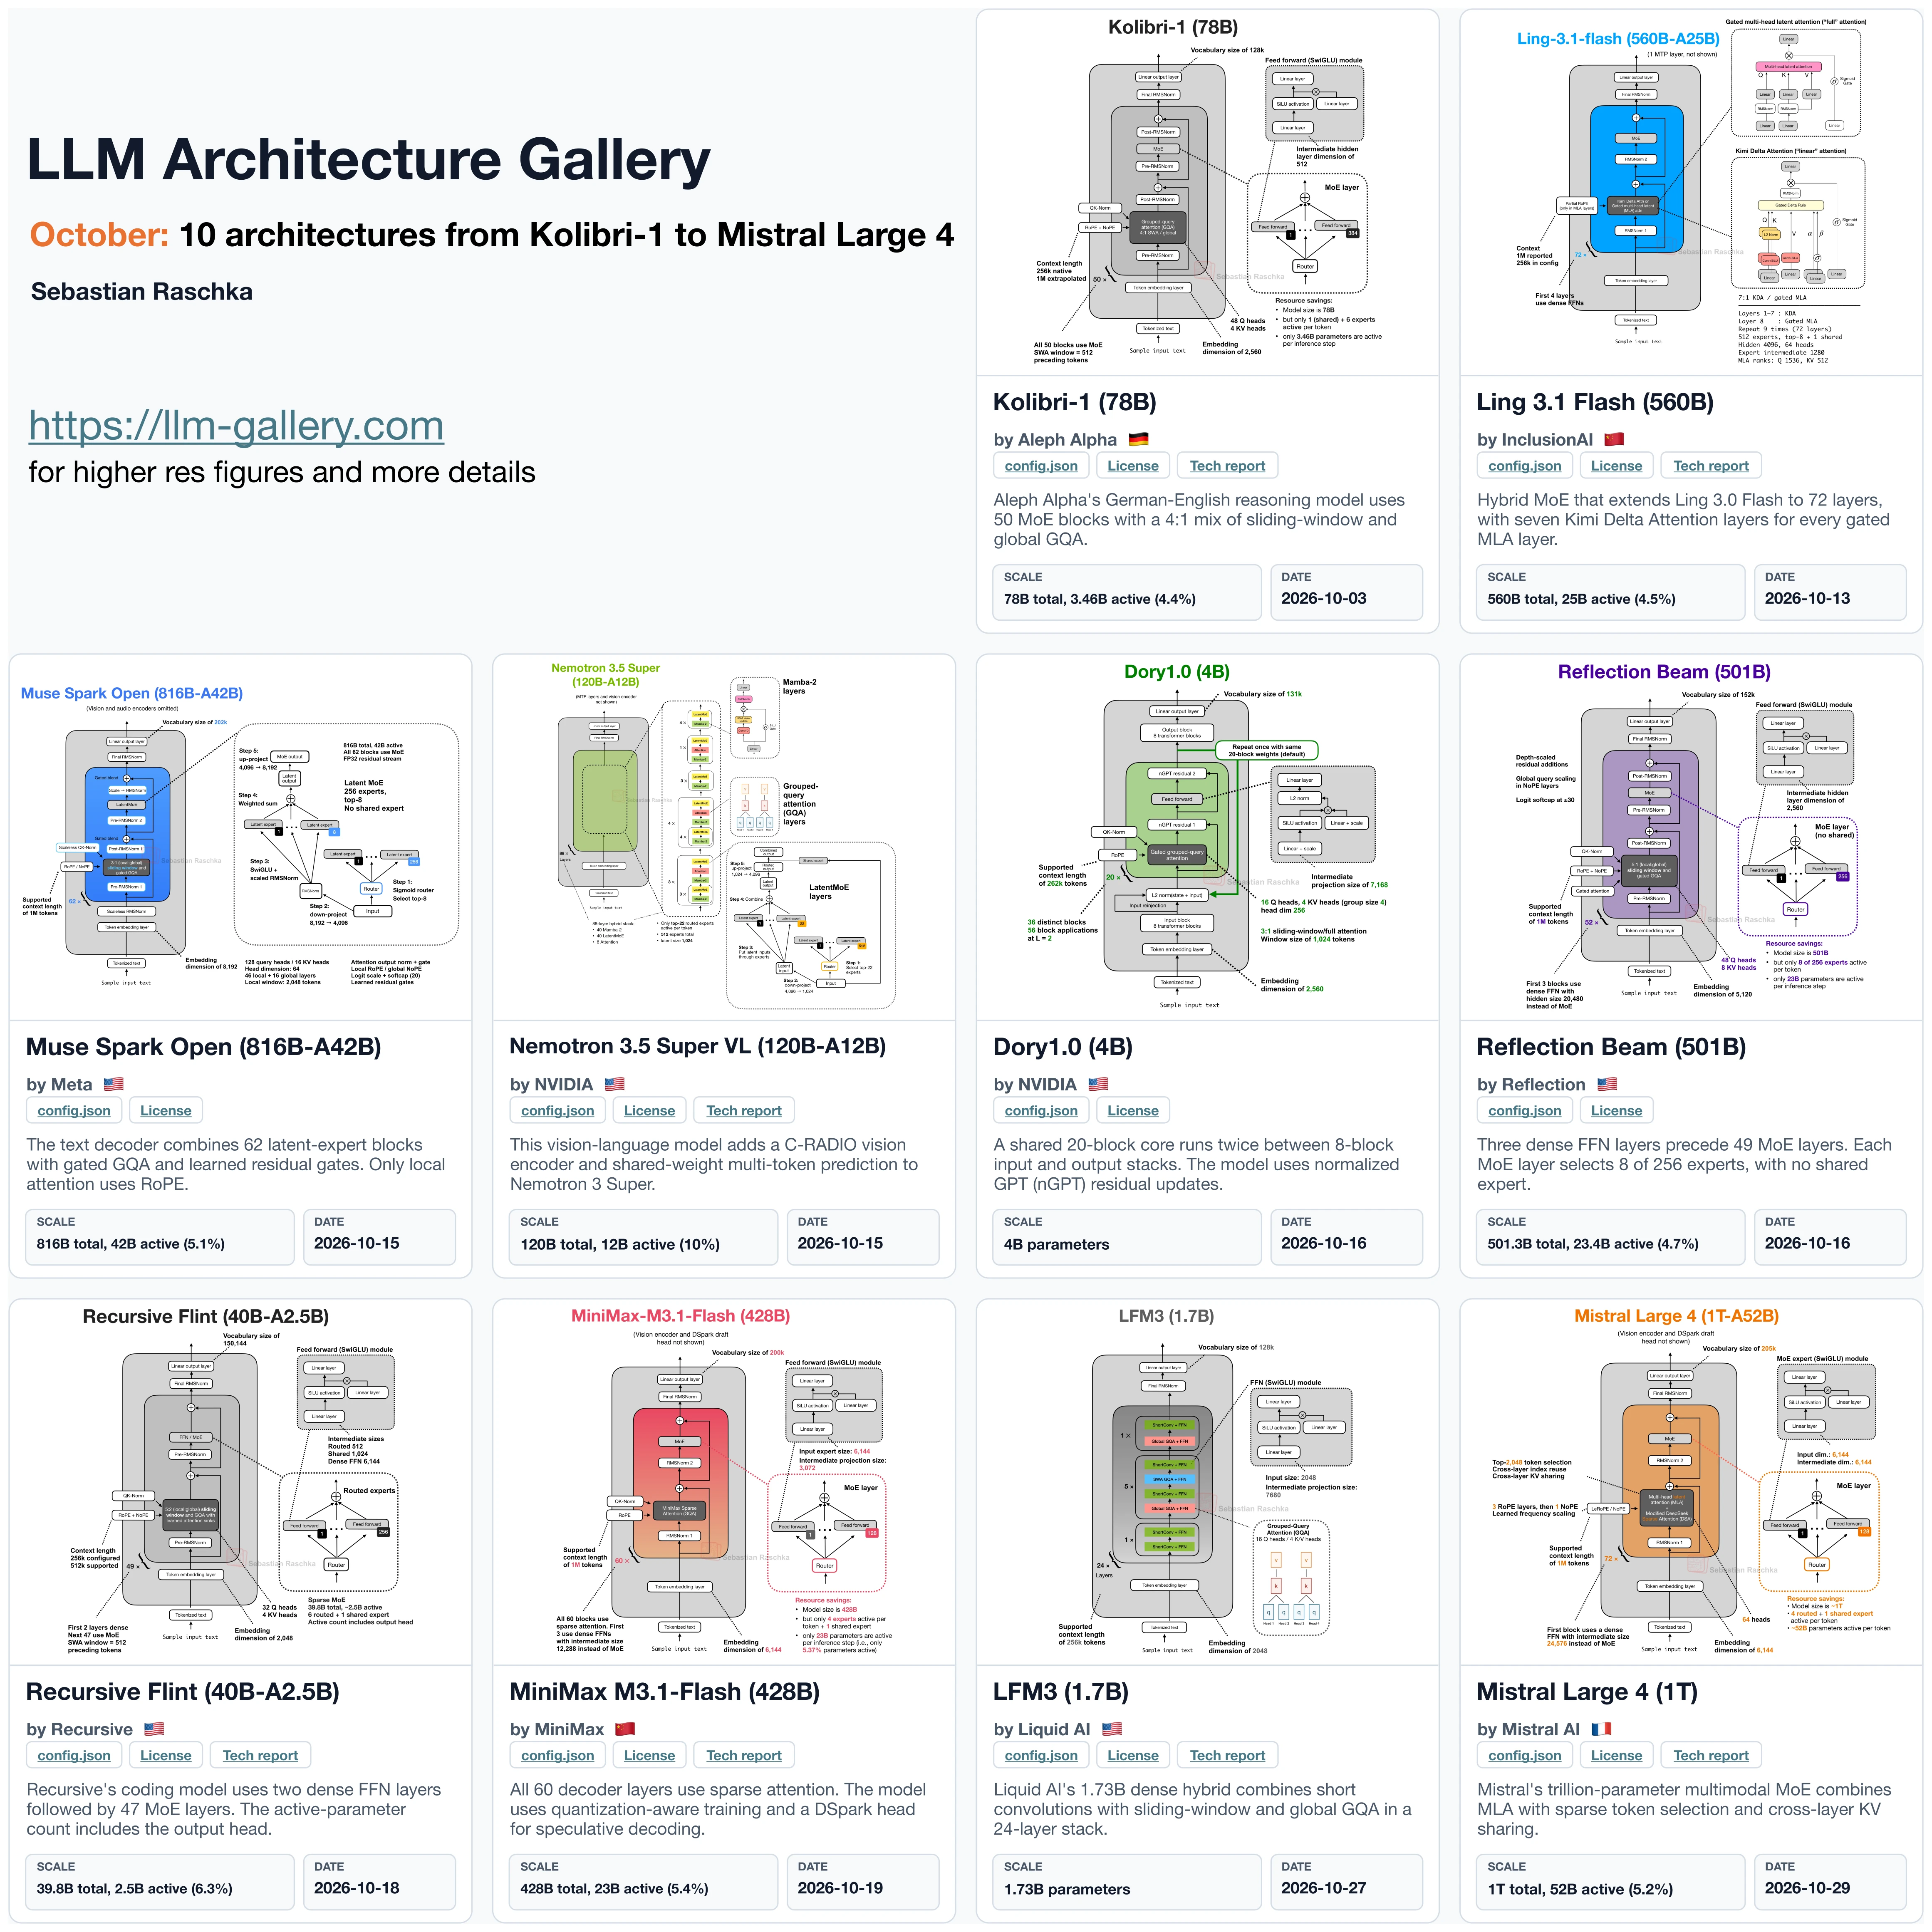 Open October LLM Architecture Roundup
A roundup of ten open-weight LLM architecture releases from October 2026, covering attention mechanisms, hybrid layers, and MoE designs.
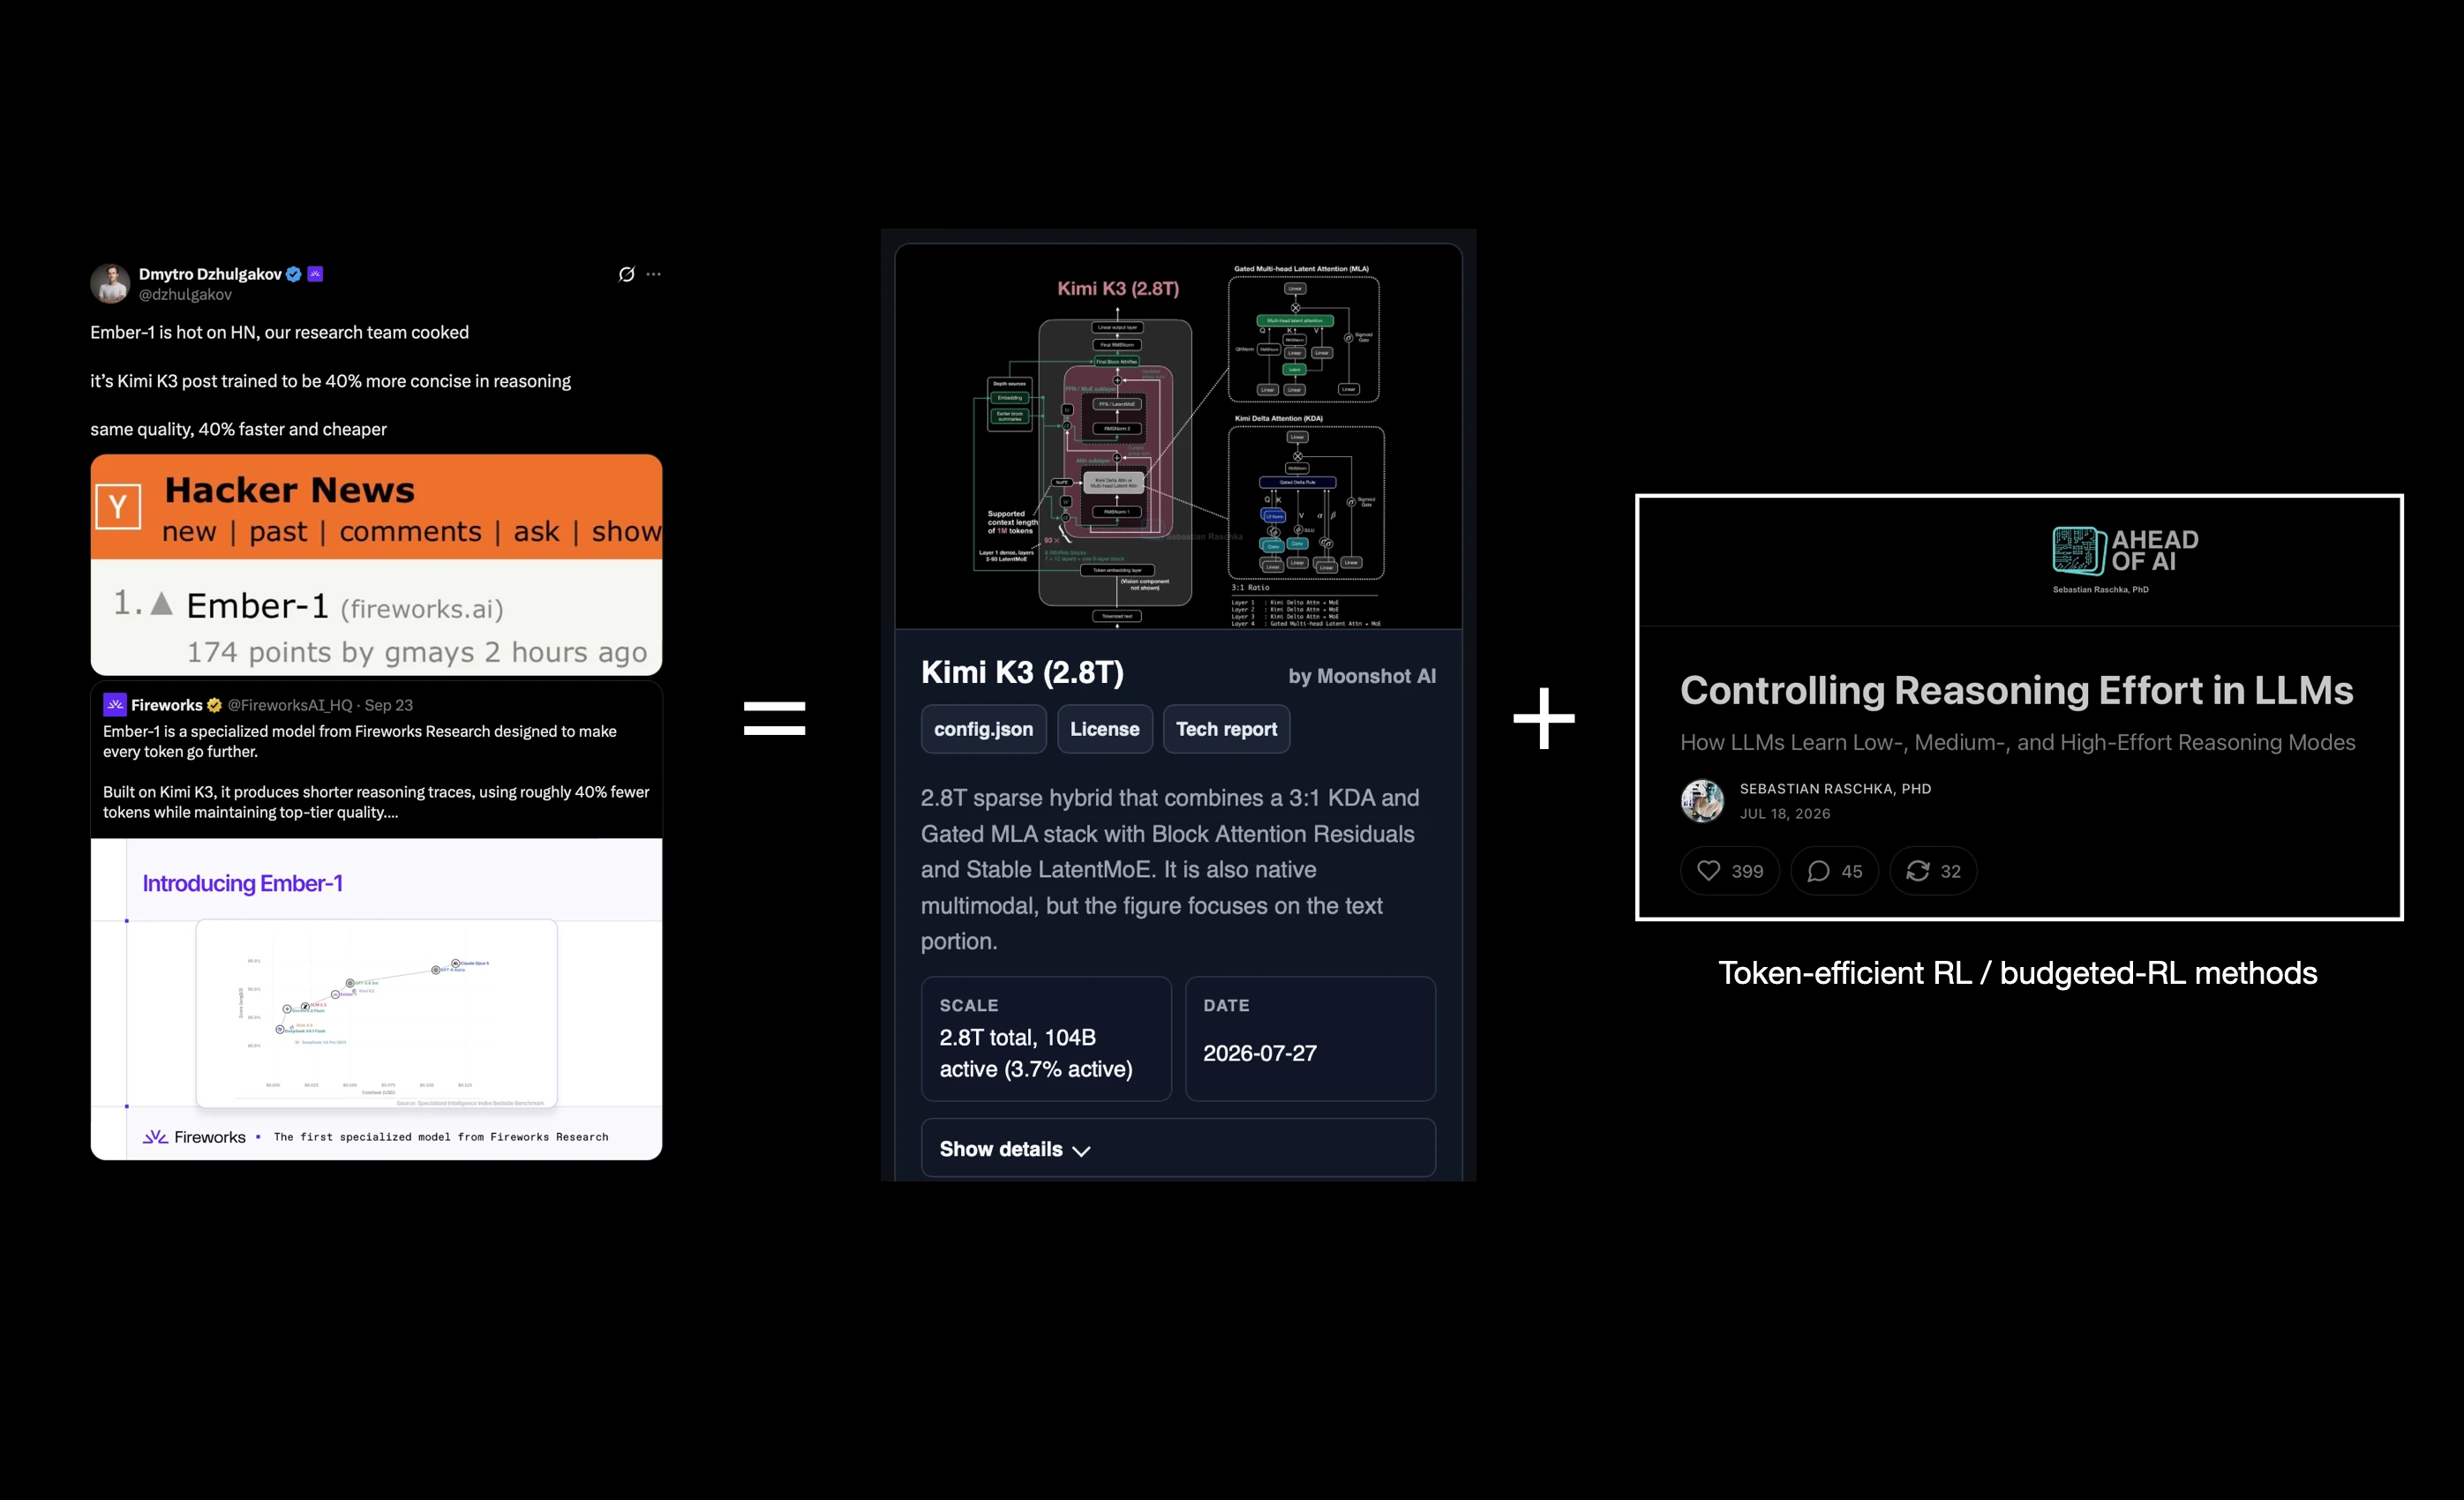 Focusing on Post-Training
Why I'd invest in post-training existing open-weight LLMs, with Fireworks' Ember-1 as an example of more token-efficient reasoning.