
Implementing LLM Architectures From Scratch
I shared a short talk on what I learned from implementing LLM architectures from scratch in Python and PyTorch.
The practical part is the workflow. When a new open-weight model comes out, I usually start from a compact reference implementation, trace the architecture changes, and compare those details against model cards, config files, and released code. This is often the fastest way to separate naming differences from actual design changes.
The talk is here: What I Learned From Implementing LLM Architectures From Scratch.
For related reading, see the recent LLM architecture developments article and the LLM Architecture Gallery.
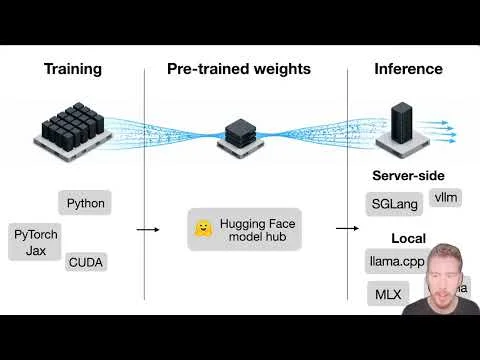
Source: lightly edited website version of my Substack note.
Read Next
 MiMo-V2.6 Pro Architecture and Training Notes
Notes on MiMo-V2.6 Pro's GQA and sliding-window attention, agent training tasks, reward signals, and large RL batches.
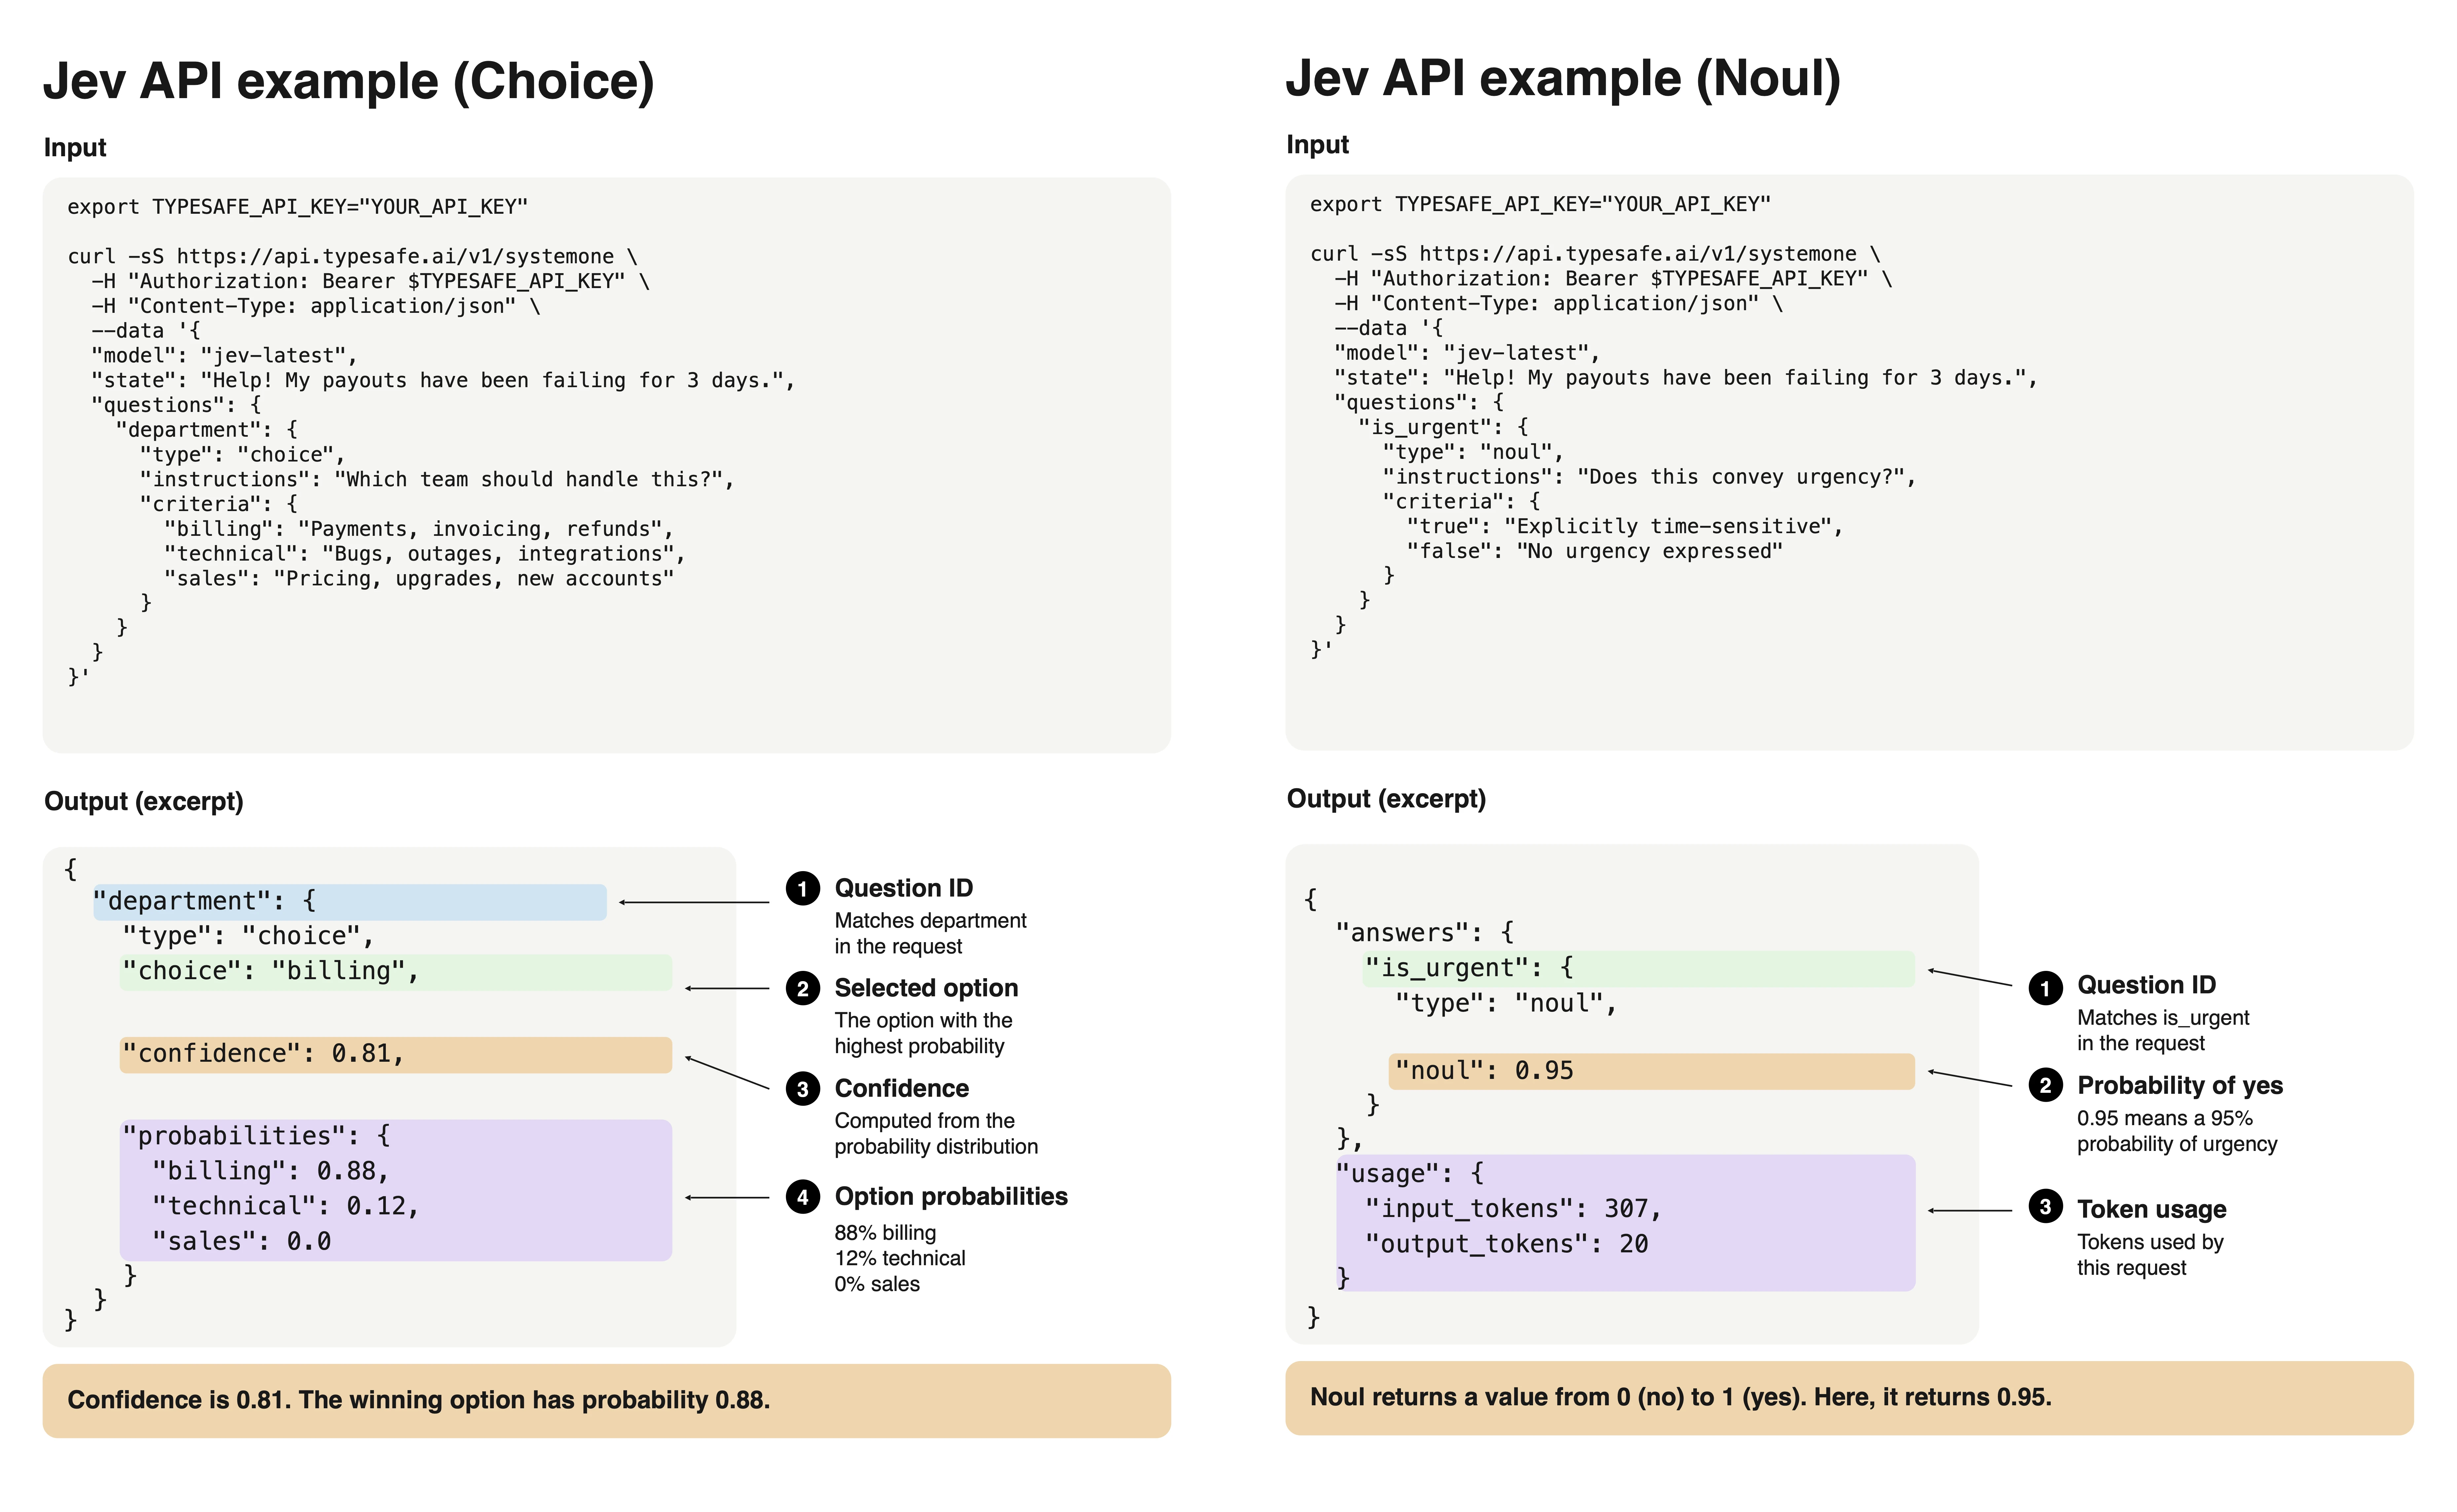 It's Easy to Dismiss Jev as Just a Classifier
A short note on Jev's generalization, possible encoder-style architecture and training, and Choice and Noul API examples.
Pacing != Pacing Development
My take on AI model pacing as a framework for release checks and the competitive pressure around model releases.