
Open October LLM Architecture Roundup
Catching up on the 10 (!) open LLM architecture releases from the past month. Quite a lot happened in October.
I guess we can call it “Open October”!
-
Kolibri-1 (78B): A notable model from Germany. Features classic Grouped Query Attention (GQA) and Sliding Window Attention (SWA) attention module.
-
Ling 3.1 Flash (560B): Uses Kimi Delta Attention and the eighth uses gated Multi-head Latent Attention (MLA) inspired by DeepSeek.
-
Muse Spark Open (816B): Besides Muse Glimmer, the first major open weight release from Meta (since Llama). Uses classic GQA + SWA but adds a LatentMoE.
-
Nemotron 3.5 Super VL (120B): Combines Mamba-2 layers with just eight attention layers. Also LatentMoE
-
Dory1.0 (4B): A looped transformer design.
-
Reflection Beam (501B): GQA+SWA architecture.
-
Recursive Flint (40B): Note that “Recursive” is the company name; the architecture is a fairly standard MoE with GQA and SWA.
-
MiniMax M3.1-Flash (428B): Uses their own MiniMax Sparse Attention module.
-
LFM3 (1.7B): Hybrid architecture that mixes short convolutions and attention.
-
Mistral Large 4 (1T) combines MLA with sparse attention.
I plan to cover/discuss things in more depth in my next Substack article in the coming weeks!
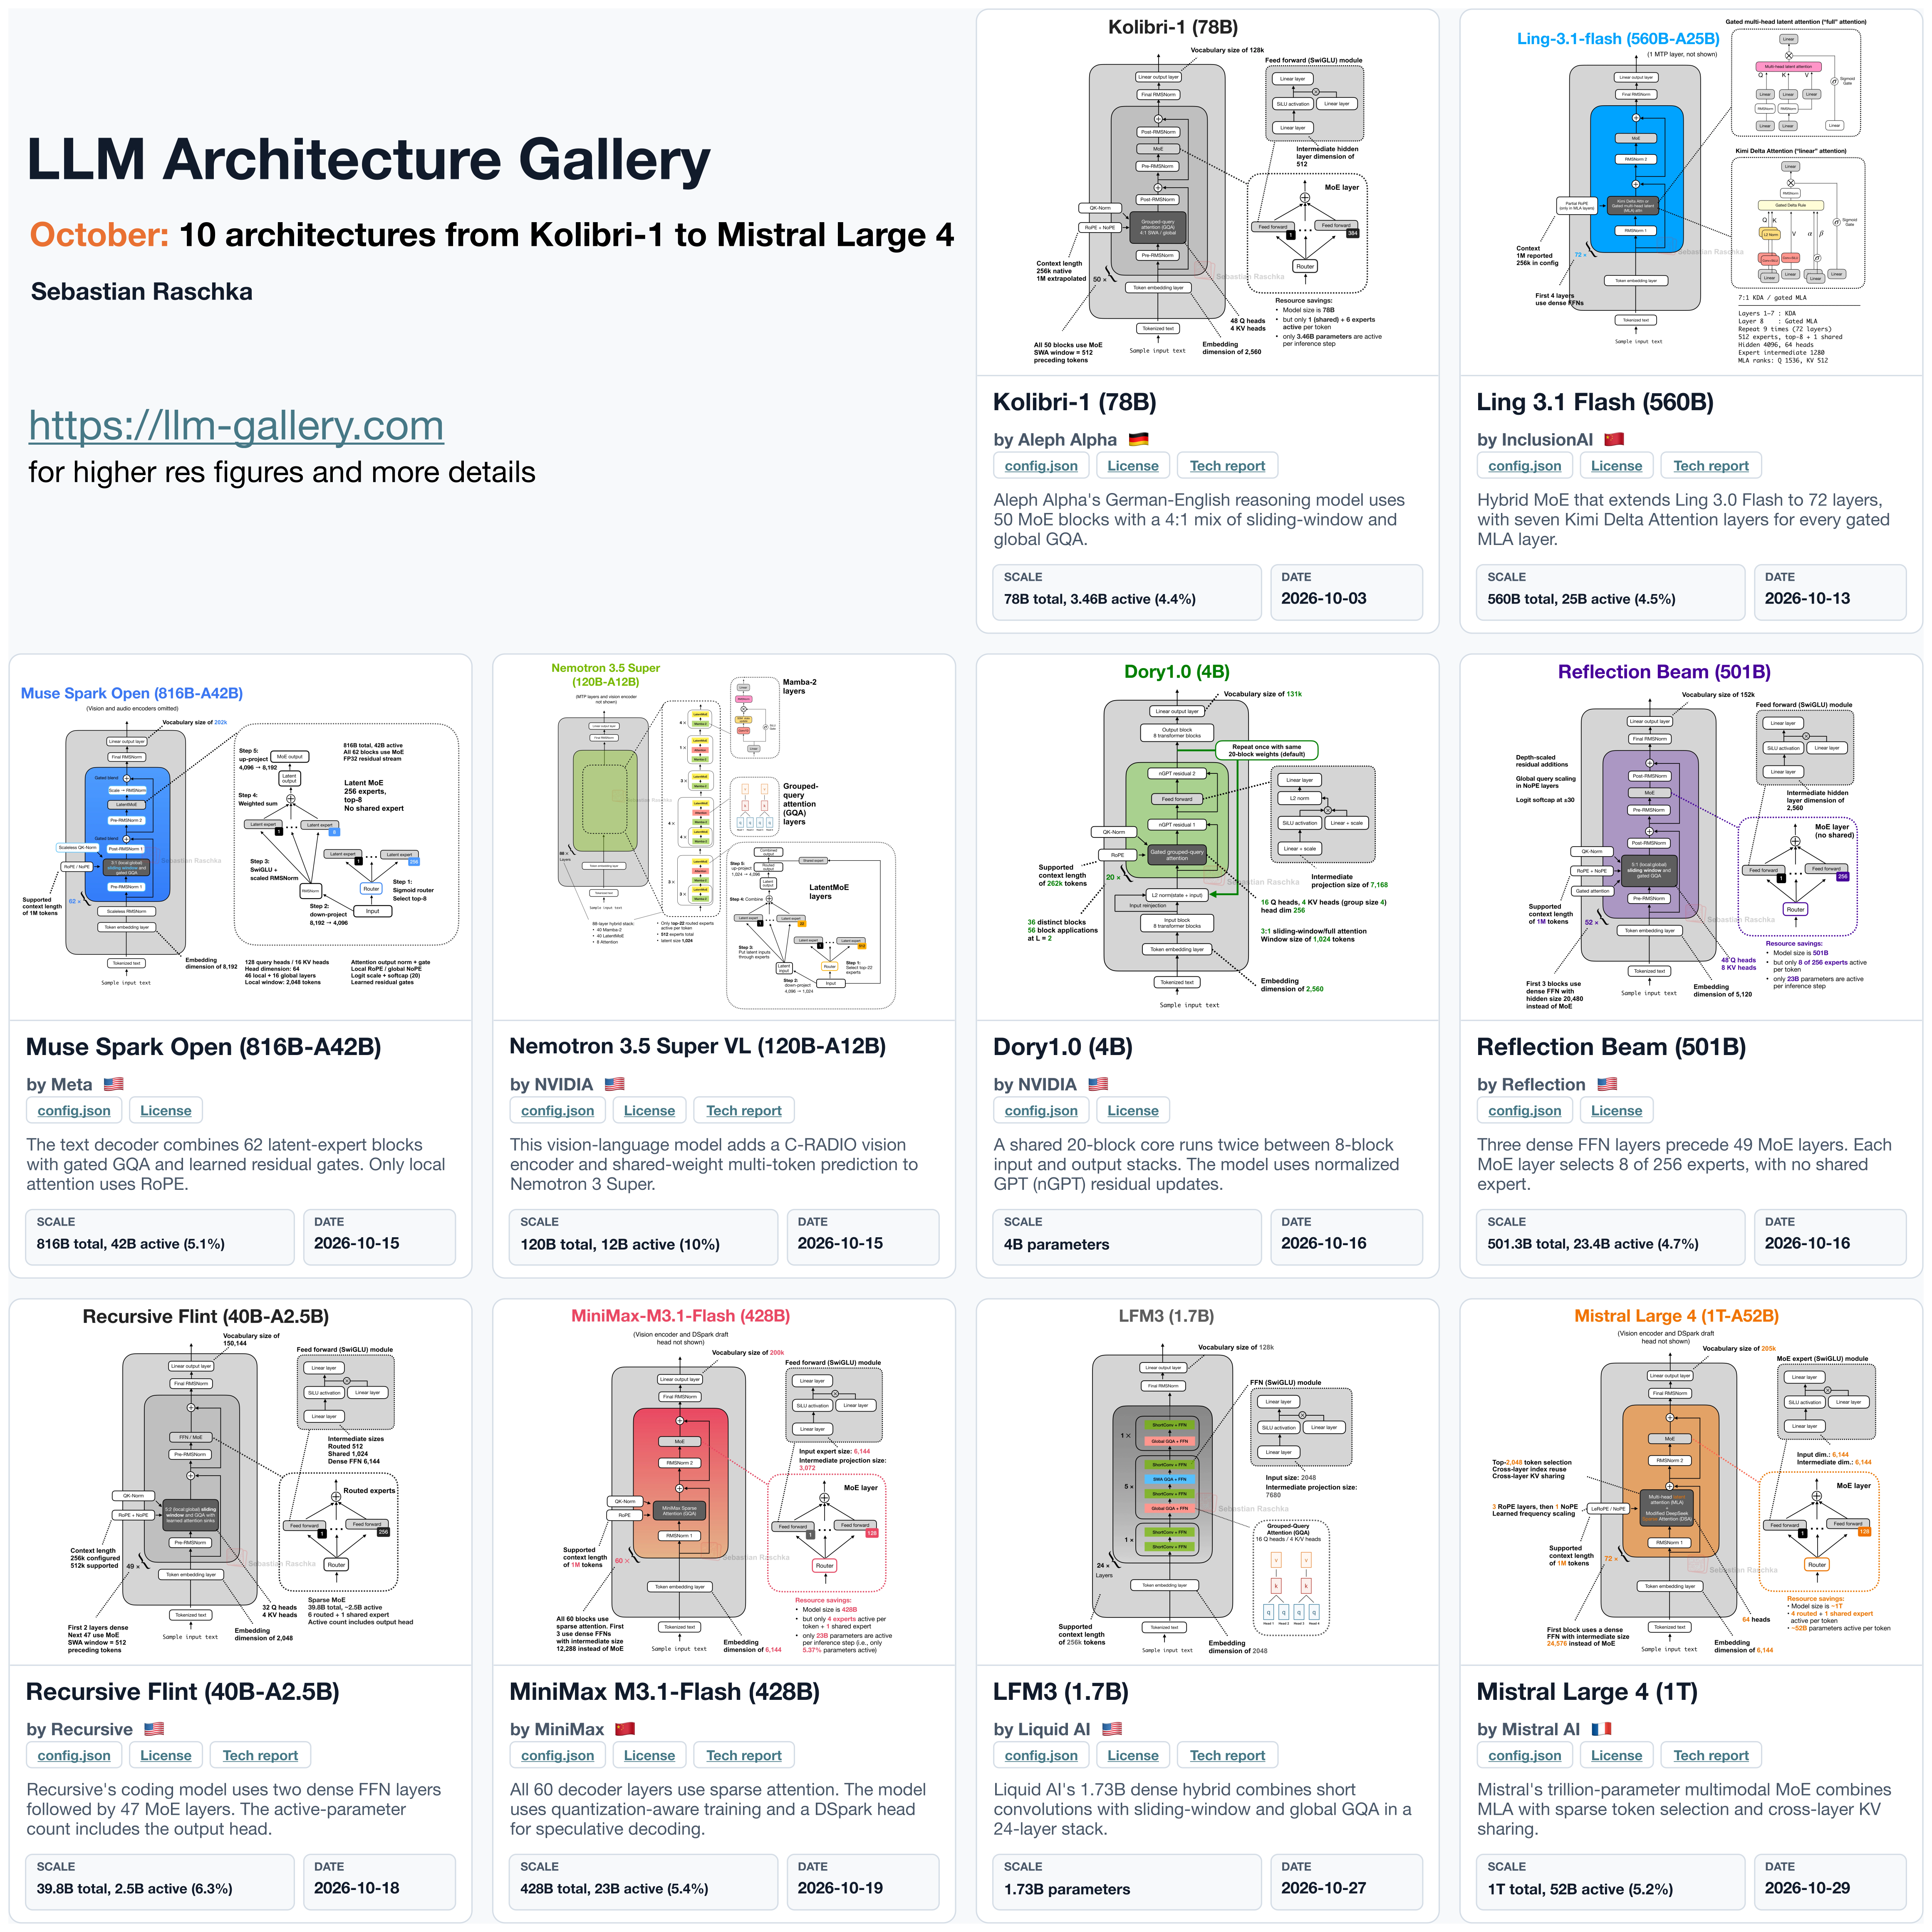
Source: lightly edited website version of my Substack note.
Read Next
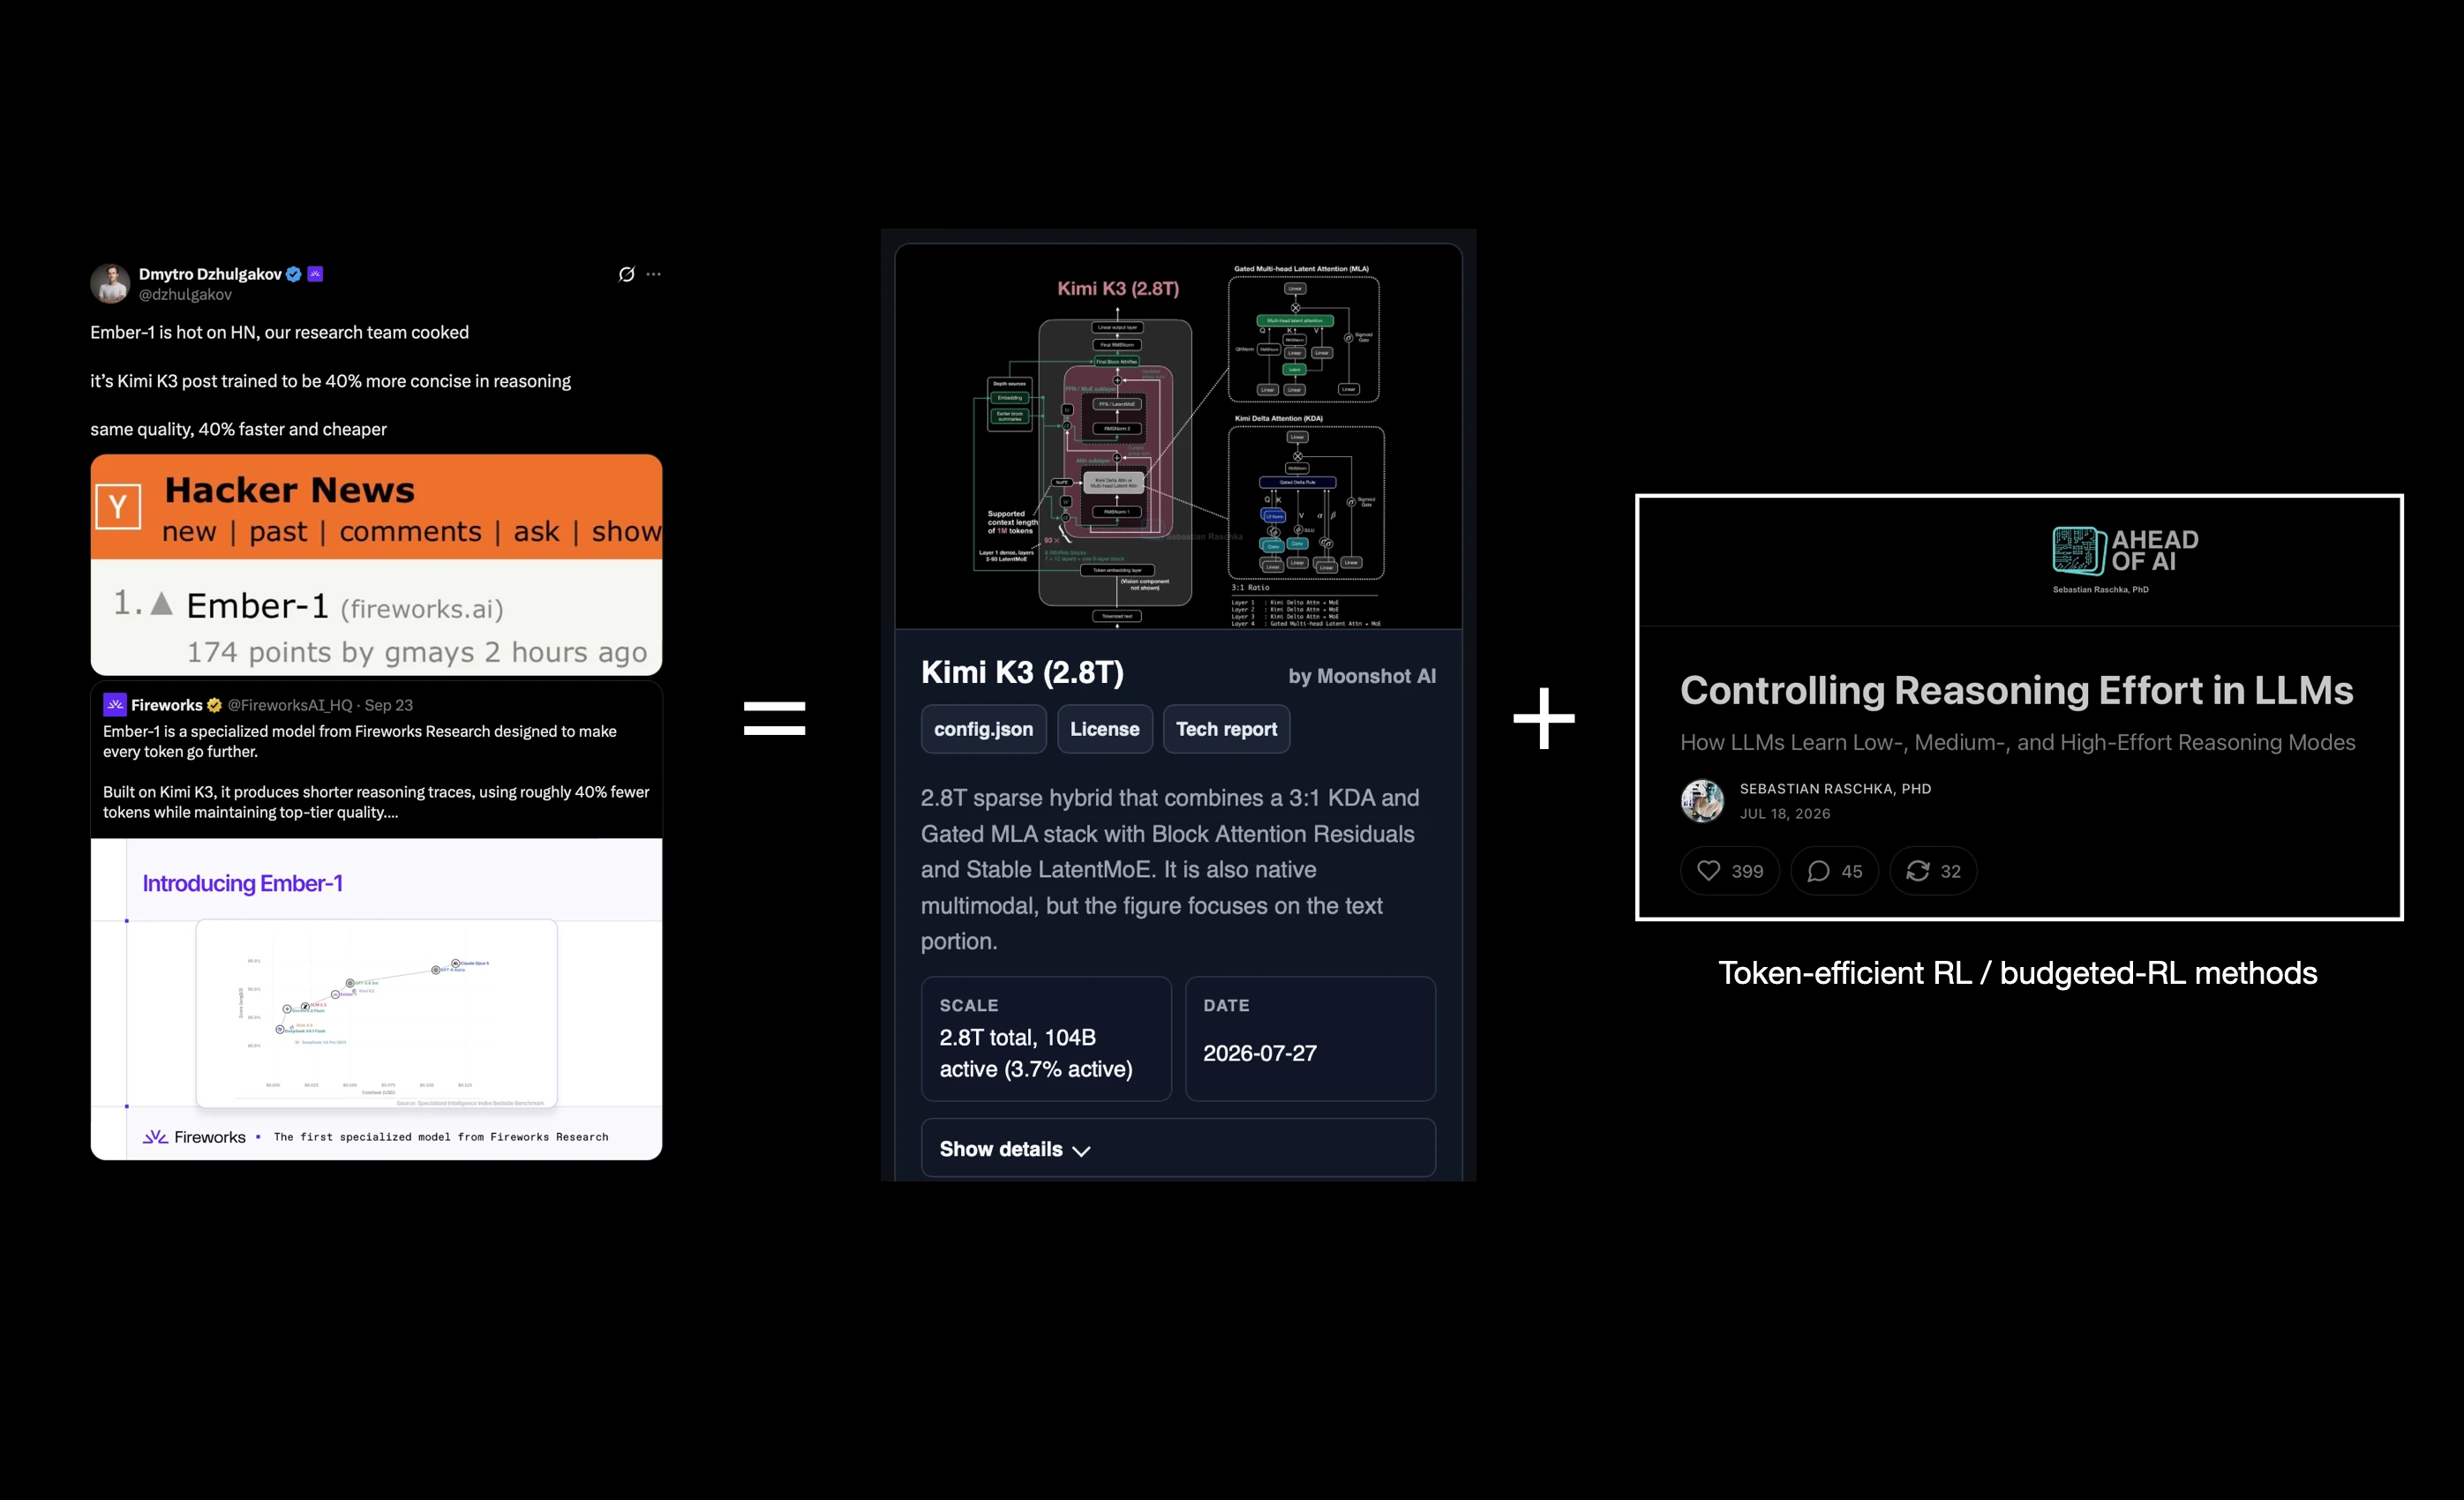 Focusing on Post-Training
Why I'd invest in post-training existing open-weight LLMs, with Fireworks' Ember-1 as an example of more token-efficient reasoning.
 MiMo-V2.6 Pro Architecture and Training Notes
Notes on MiMo-V2.6 Pro's GQA and sliding-window attention, agent training tasks, reward signals, and large RL batches.
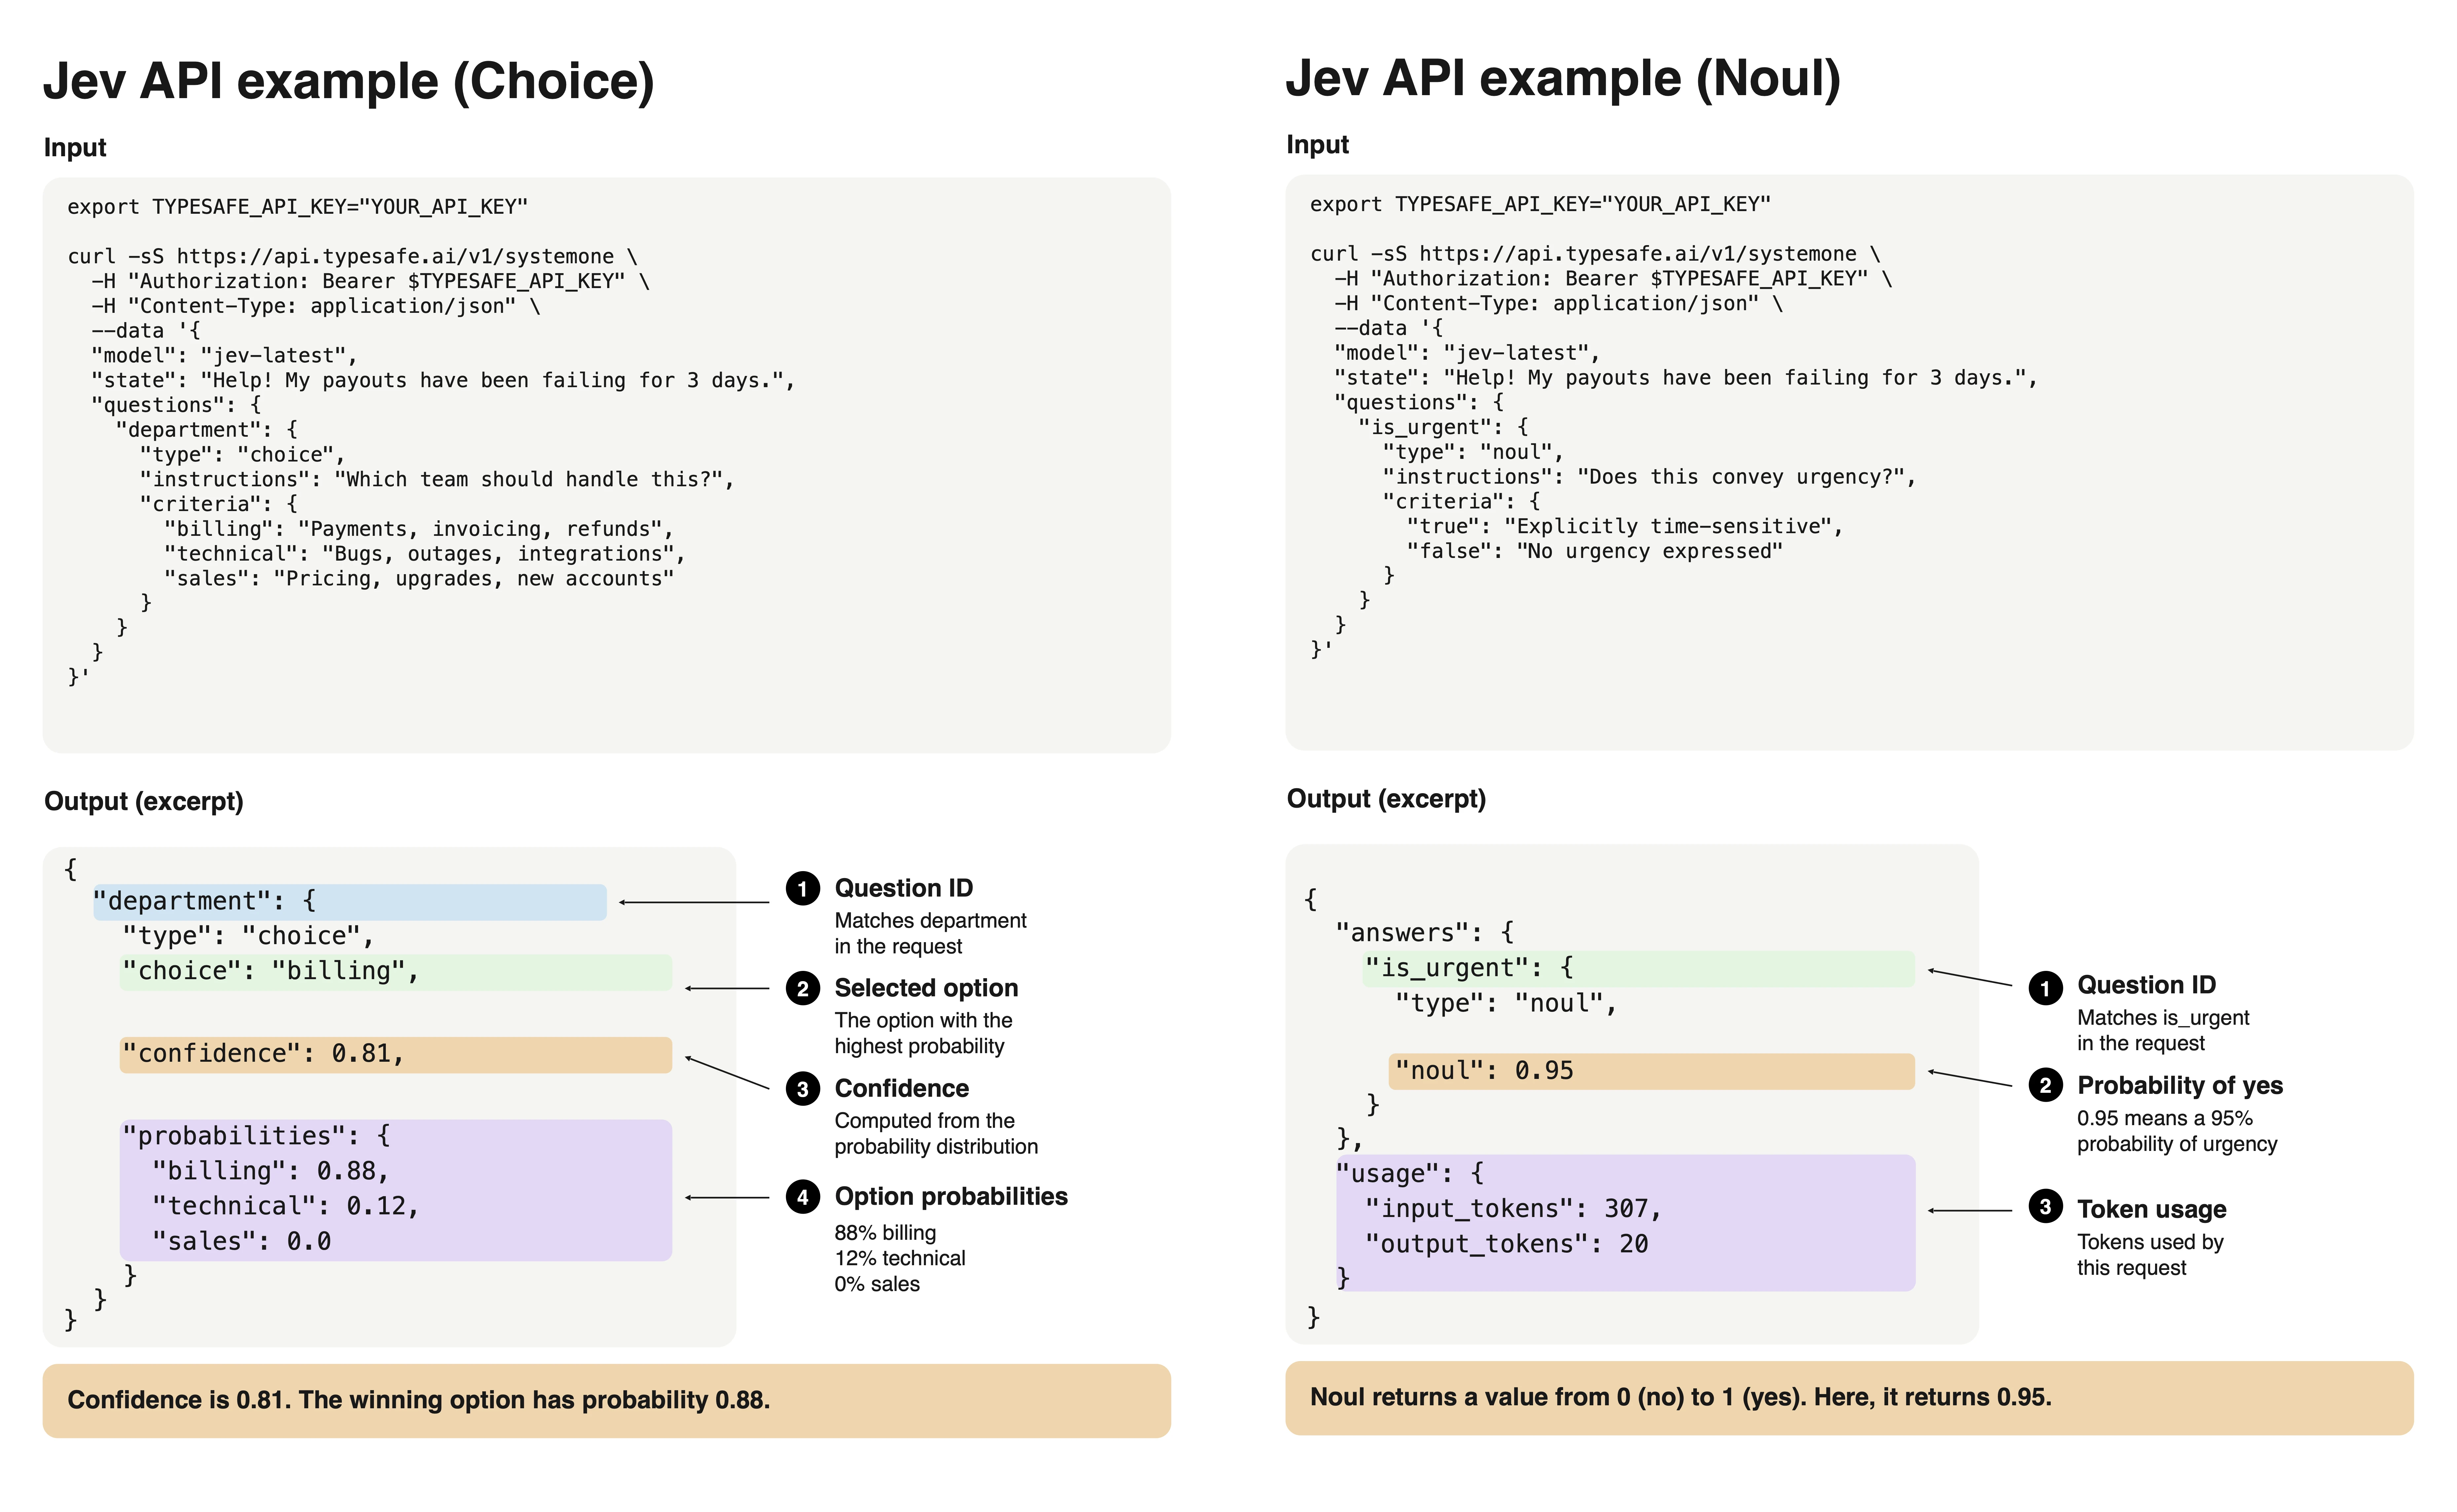 It's Easy to Dismiss Jev as Just a Classifier
A short note on Jev's generalization, possible encoder-style architecture and training, and Choice and Noul API examples.