
GLM-5.3-Flash Architecture Notes
Now we know: The popular Ox Alpha LLM was GLM-5.3-Flash…
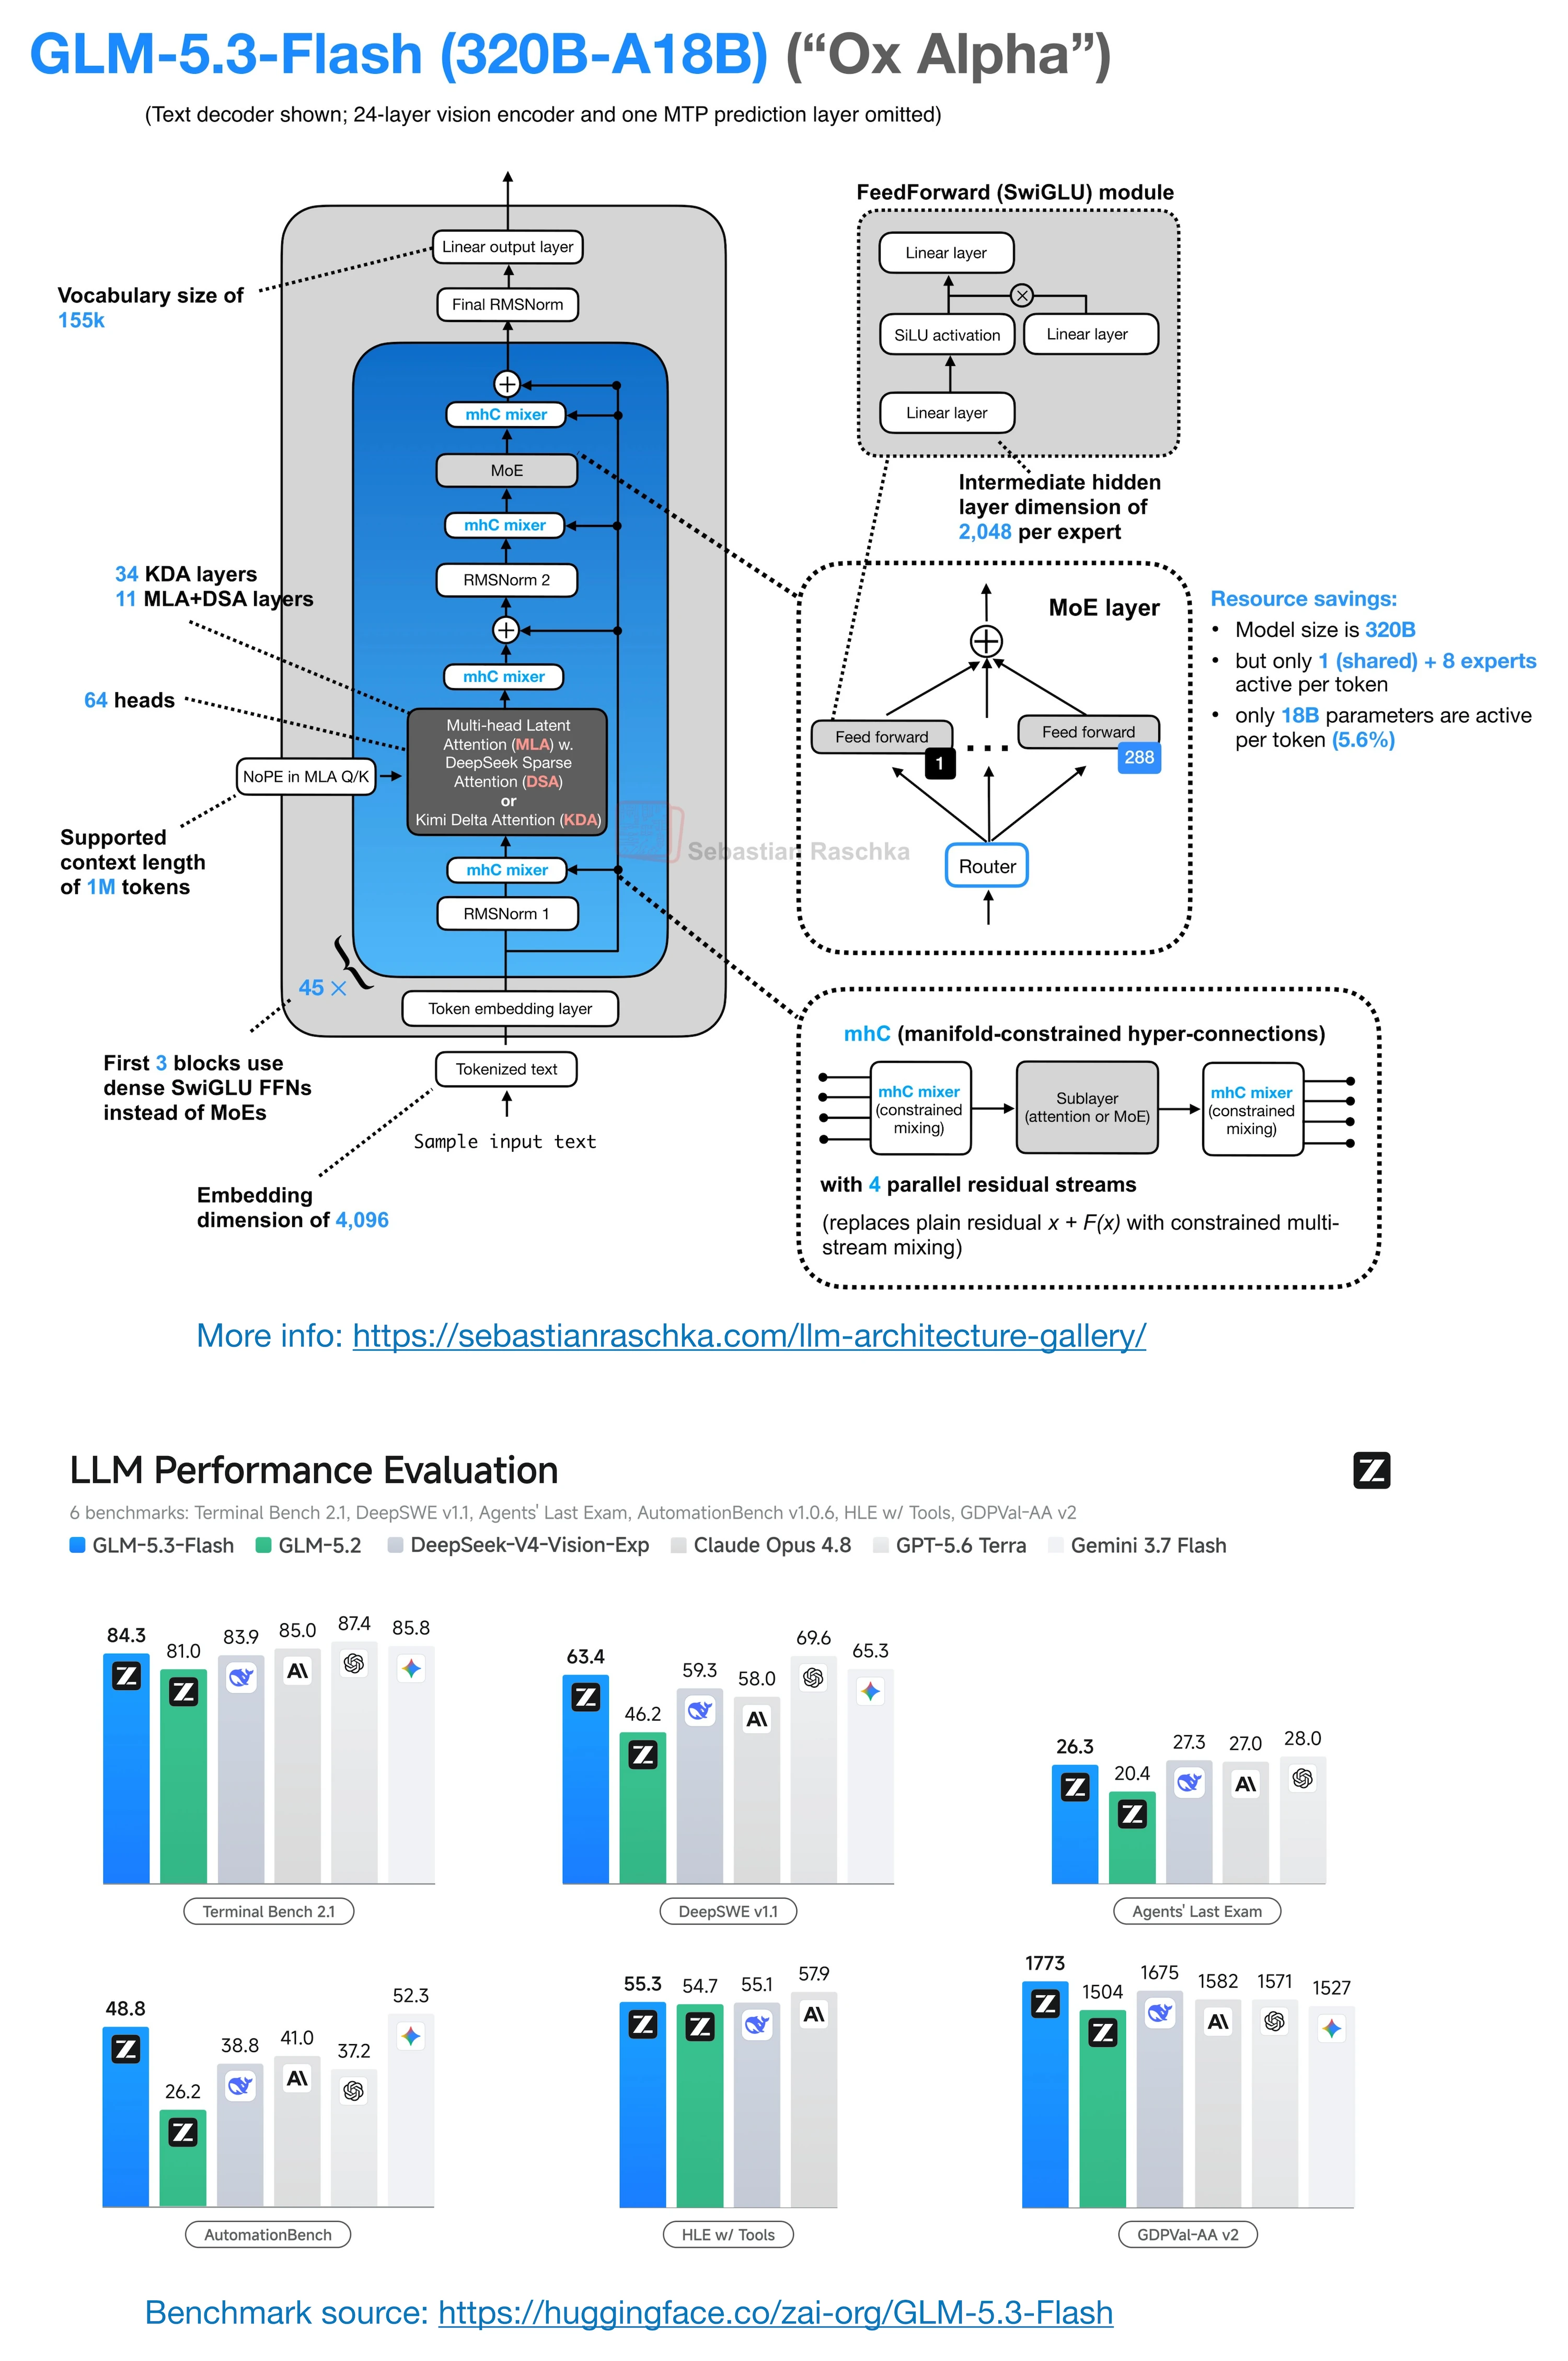
Compared to GLM-5.2, this new GLM-5.3-Flash model uses:
-
a Kimi Linear-style 3:1 (super*) hybrid attention pattern with 34 Kimi Delta Attention layers (KDA) and 11 Multi-head Latent Attention (MLA) / DeepSeek Sparse Attention (DSA) layers;
-
a scaled-down GLM-5.2-style sparse MoE backbone, going from 744B-A40B to 320B-A18B;
-
a DeepSeek V4-style mHC residual path with four parallel streams;
-
plus a native vision encoder (not shown).
I called it a “super hybrid” above because both KDA and MLA/DSA are “efficient” components. E.g., Kimi only uses KDA + full attention MLA, DeepSeek V3.2 uses DSA + full attention MLA.
PS: I’m sorry for the excessive tech jargon. Explainers on all these components (MLA, DSA, KDA, mhC, etc.) in my LLM Architecture Gallery.
PPS: Haha, maybe justification for getting that pricey Mac Studio M5 Ultra 256 GB / 512 GB to run this locally…
Source: website version of my Substack note.
Read Next
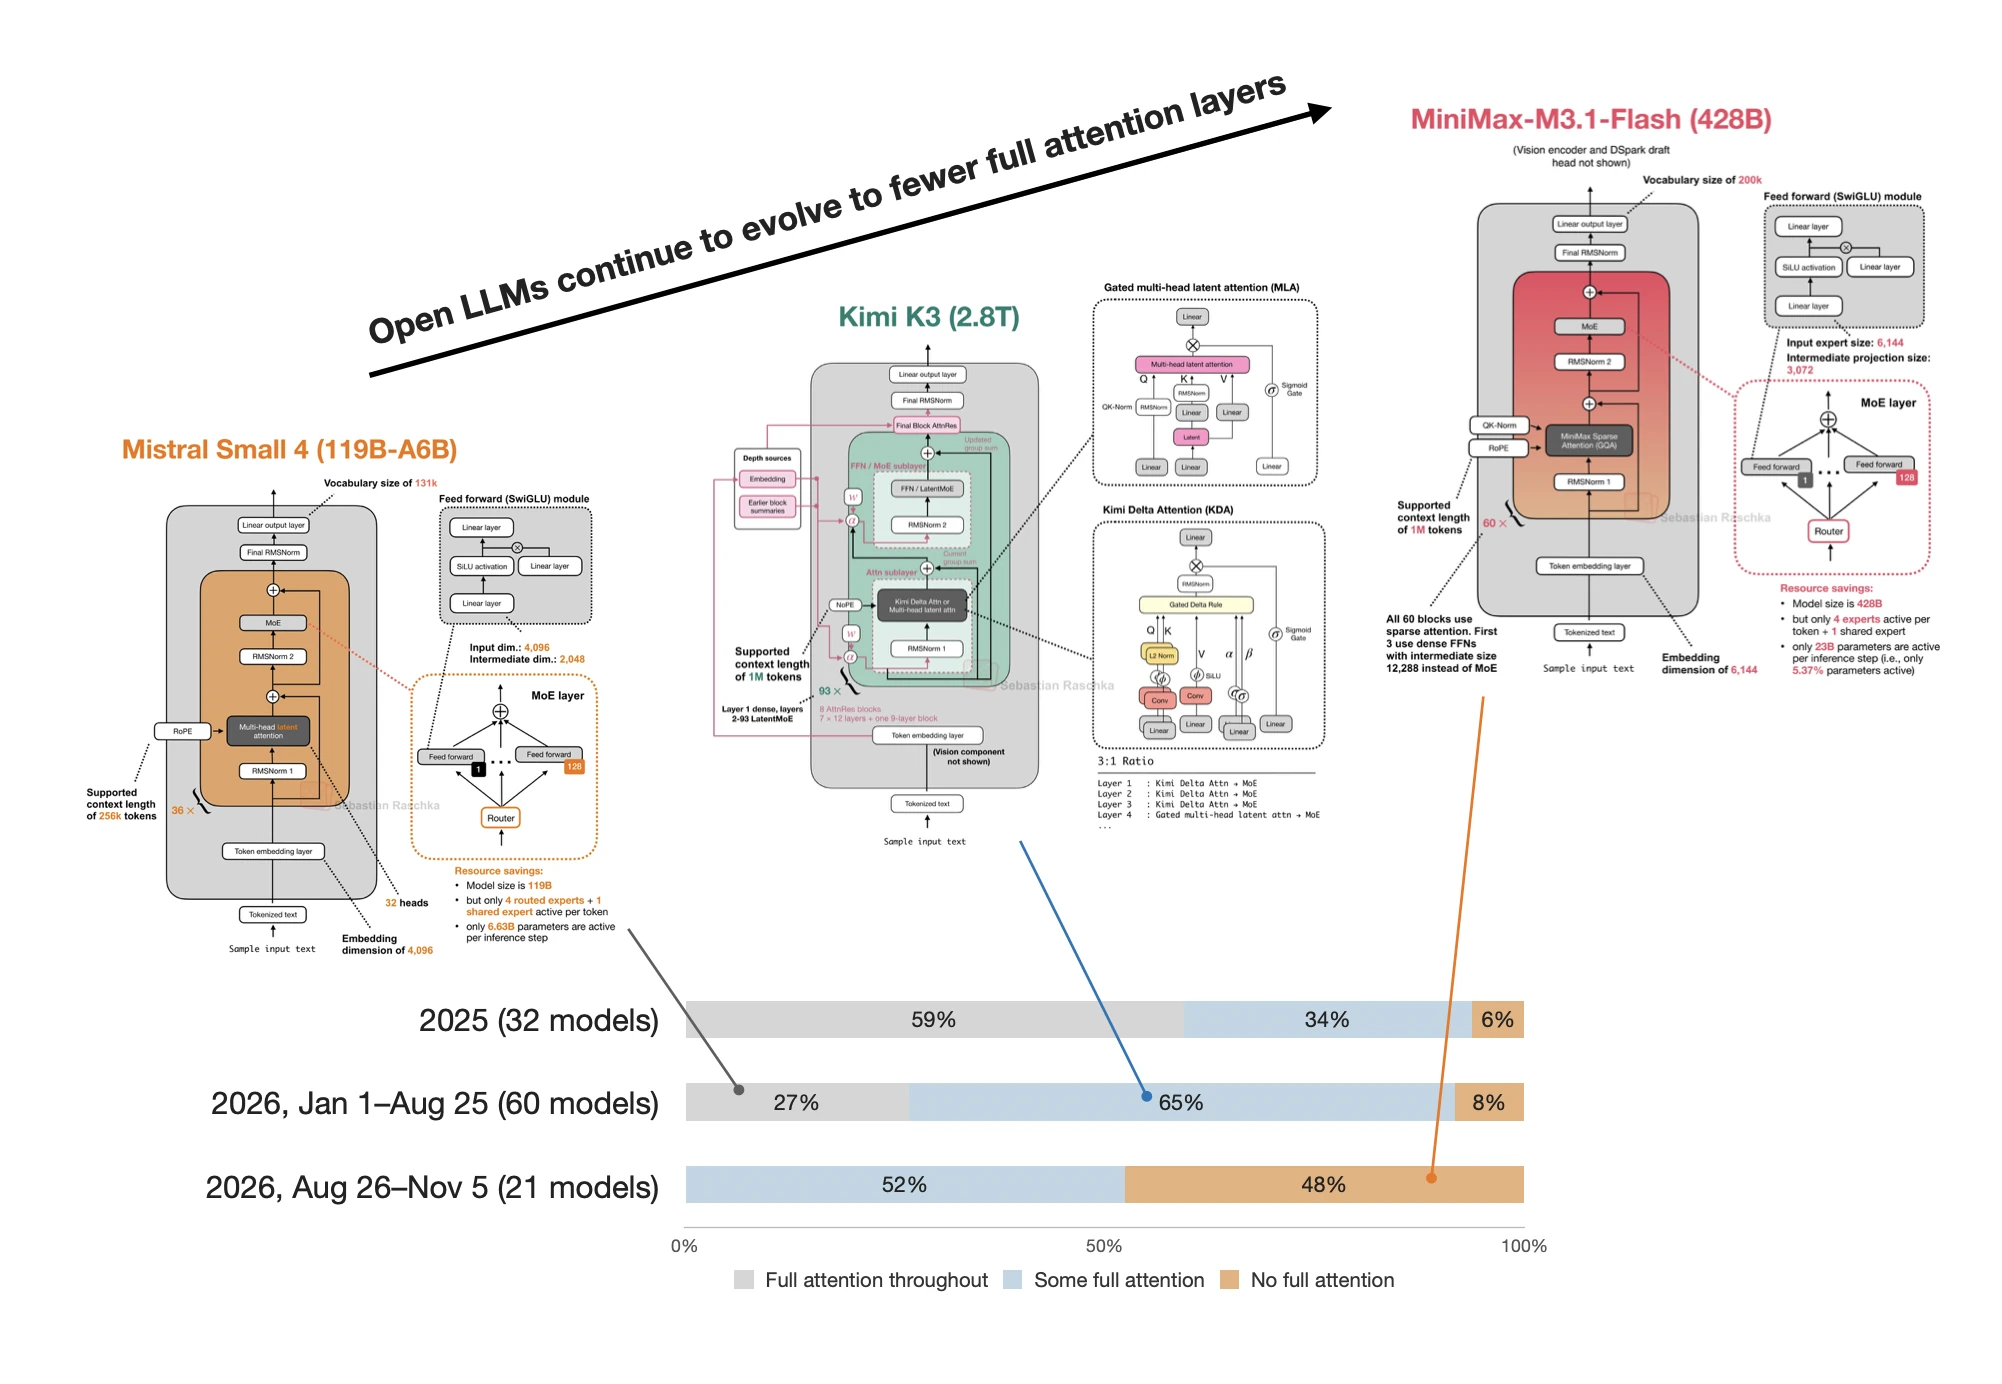 From Full to Hybrid Attention in LLMs
How open-weight LLMs are shifting from full attention to hybrid and sparse designs, and what that means for long-context compute and memory.
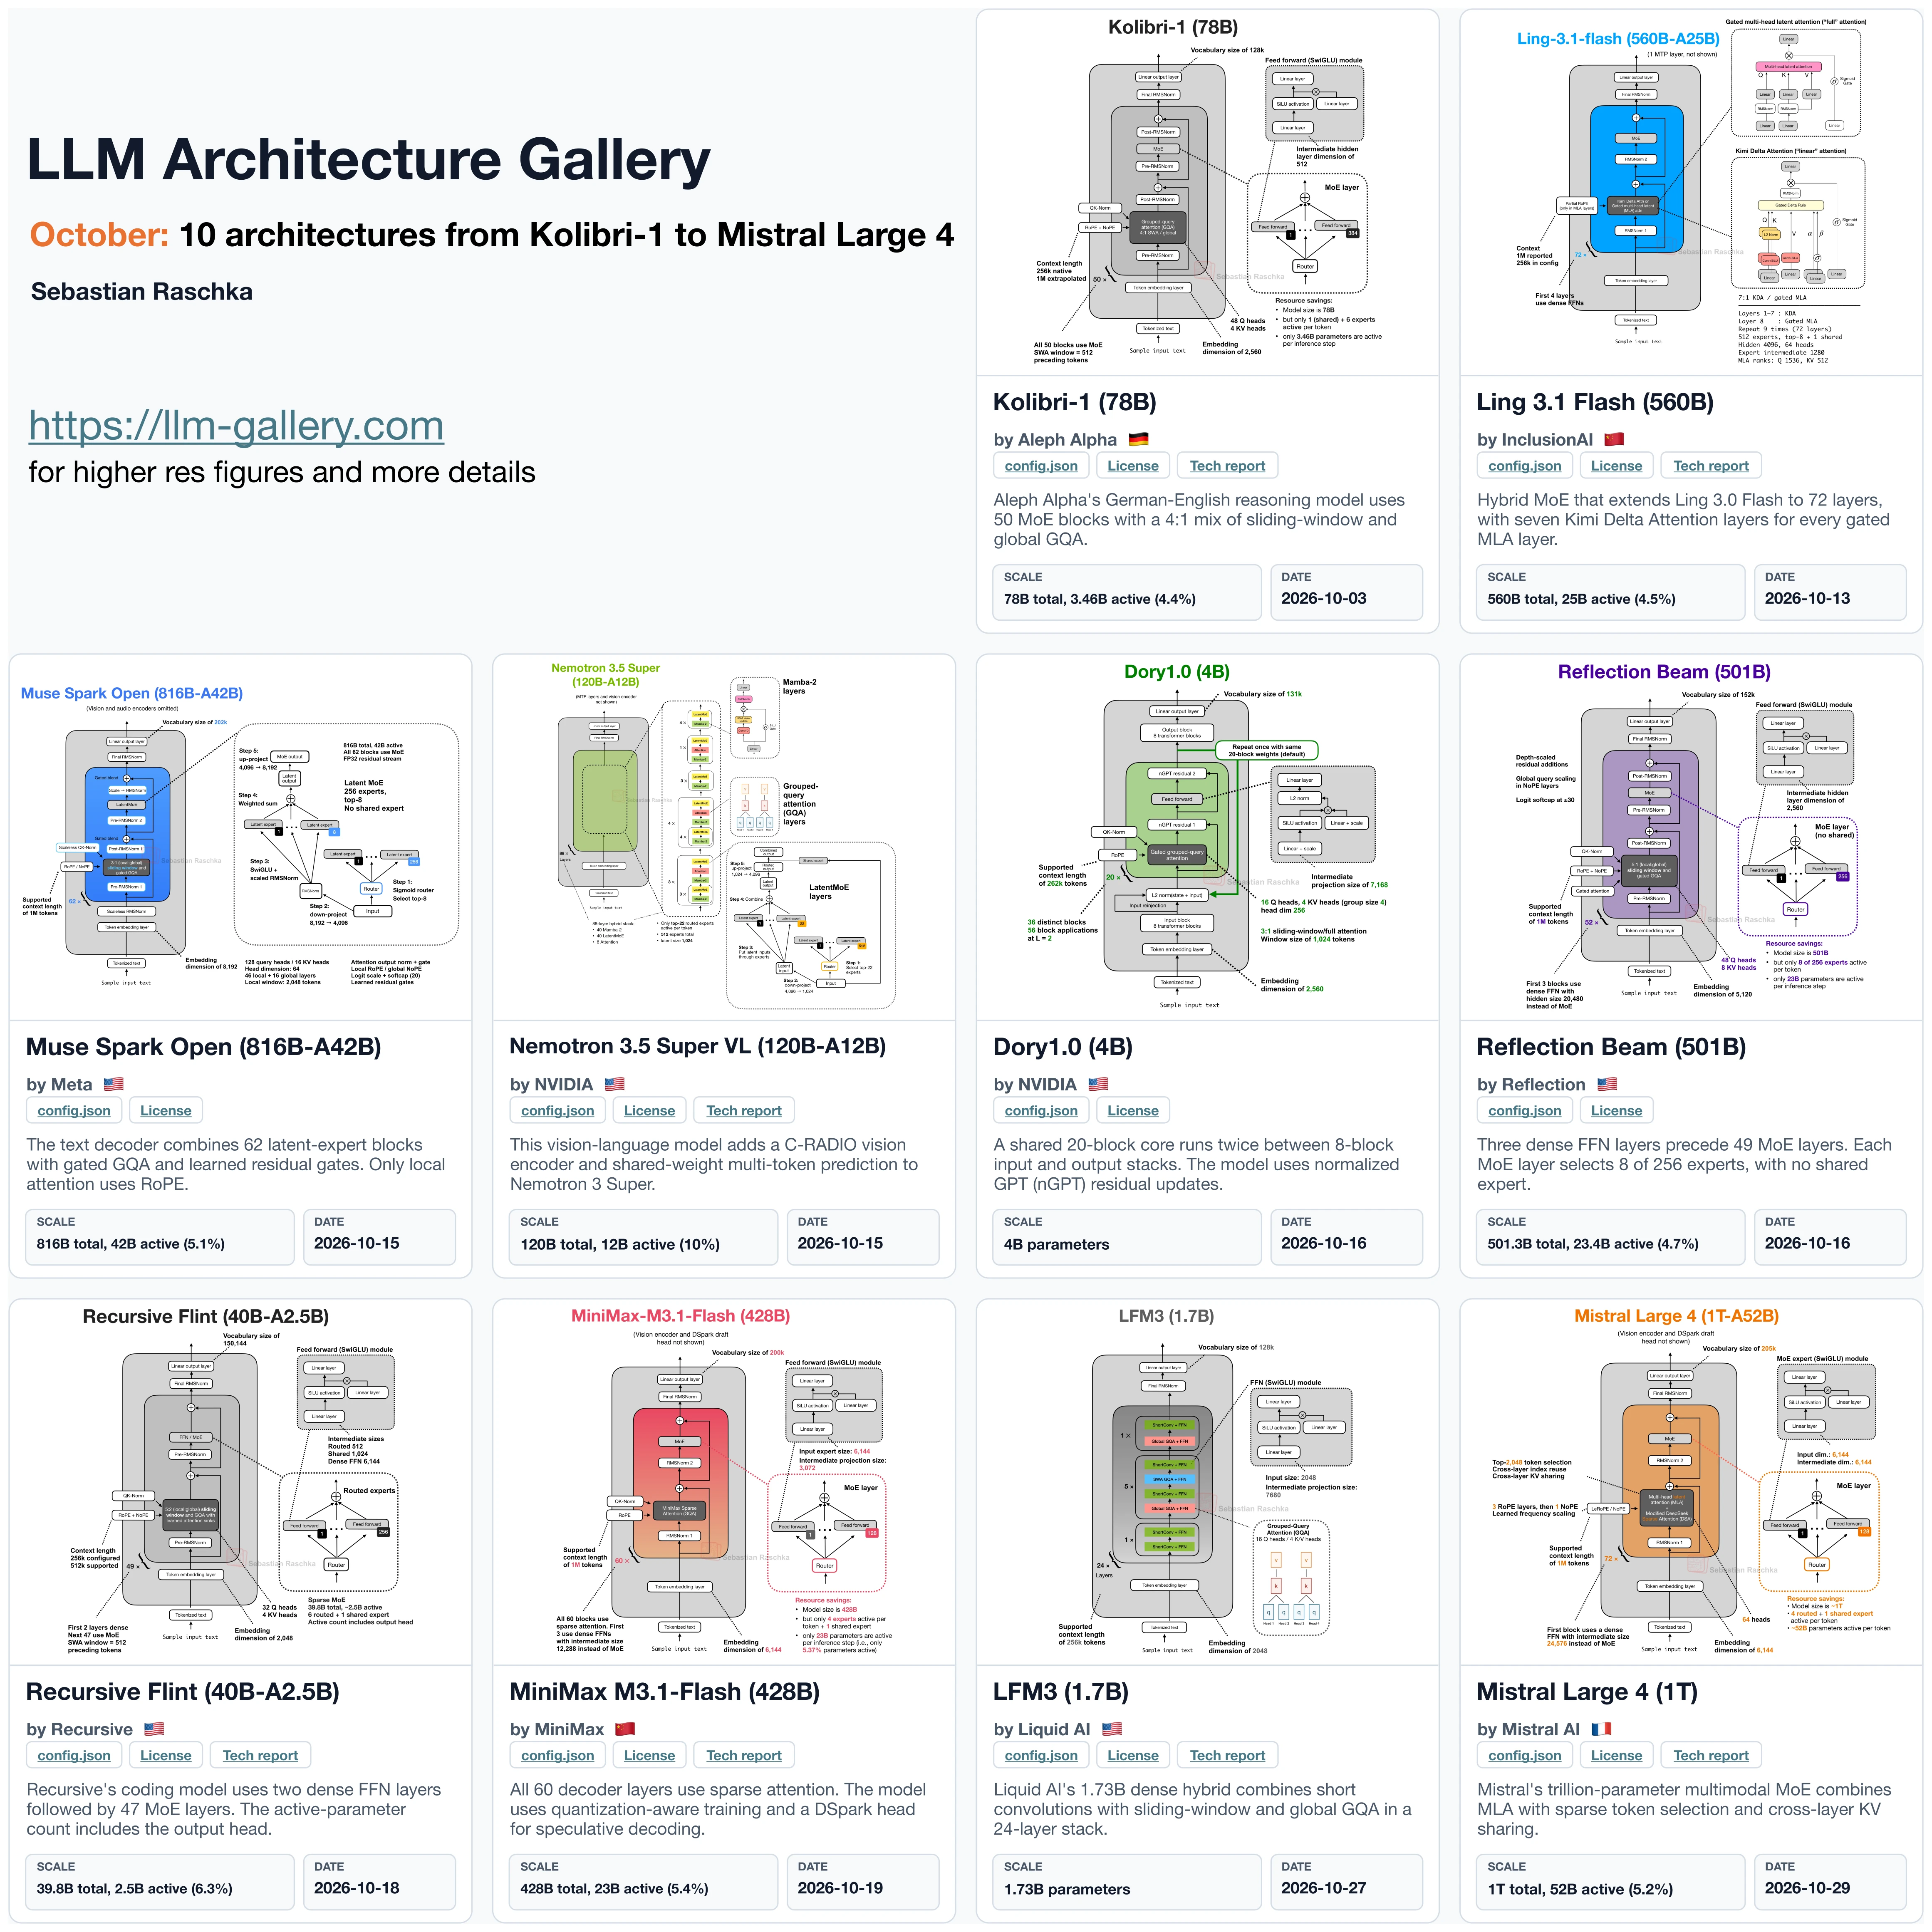 Open October LLM Architecture Roundup
A roundup of ten open-weight LLM architecture releases from October 2026, covering attention mechanisms, hybrid layers, and MoE designs.
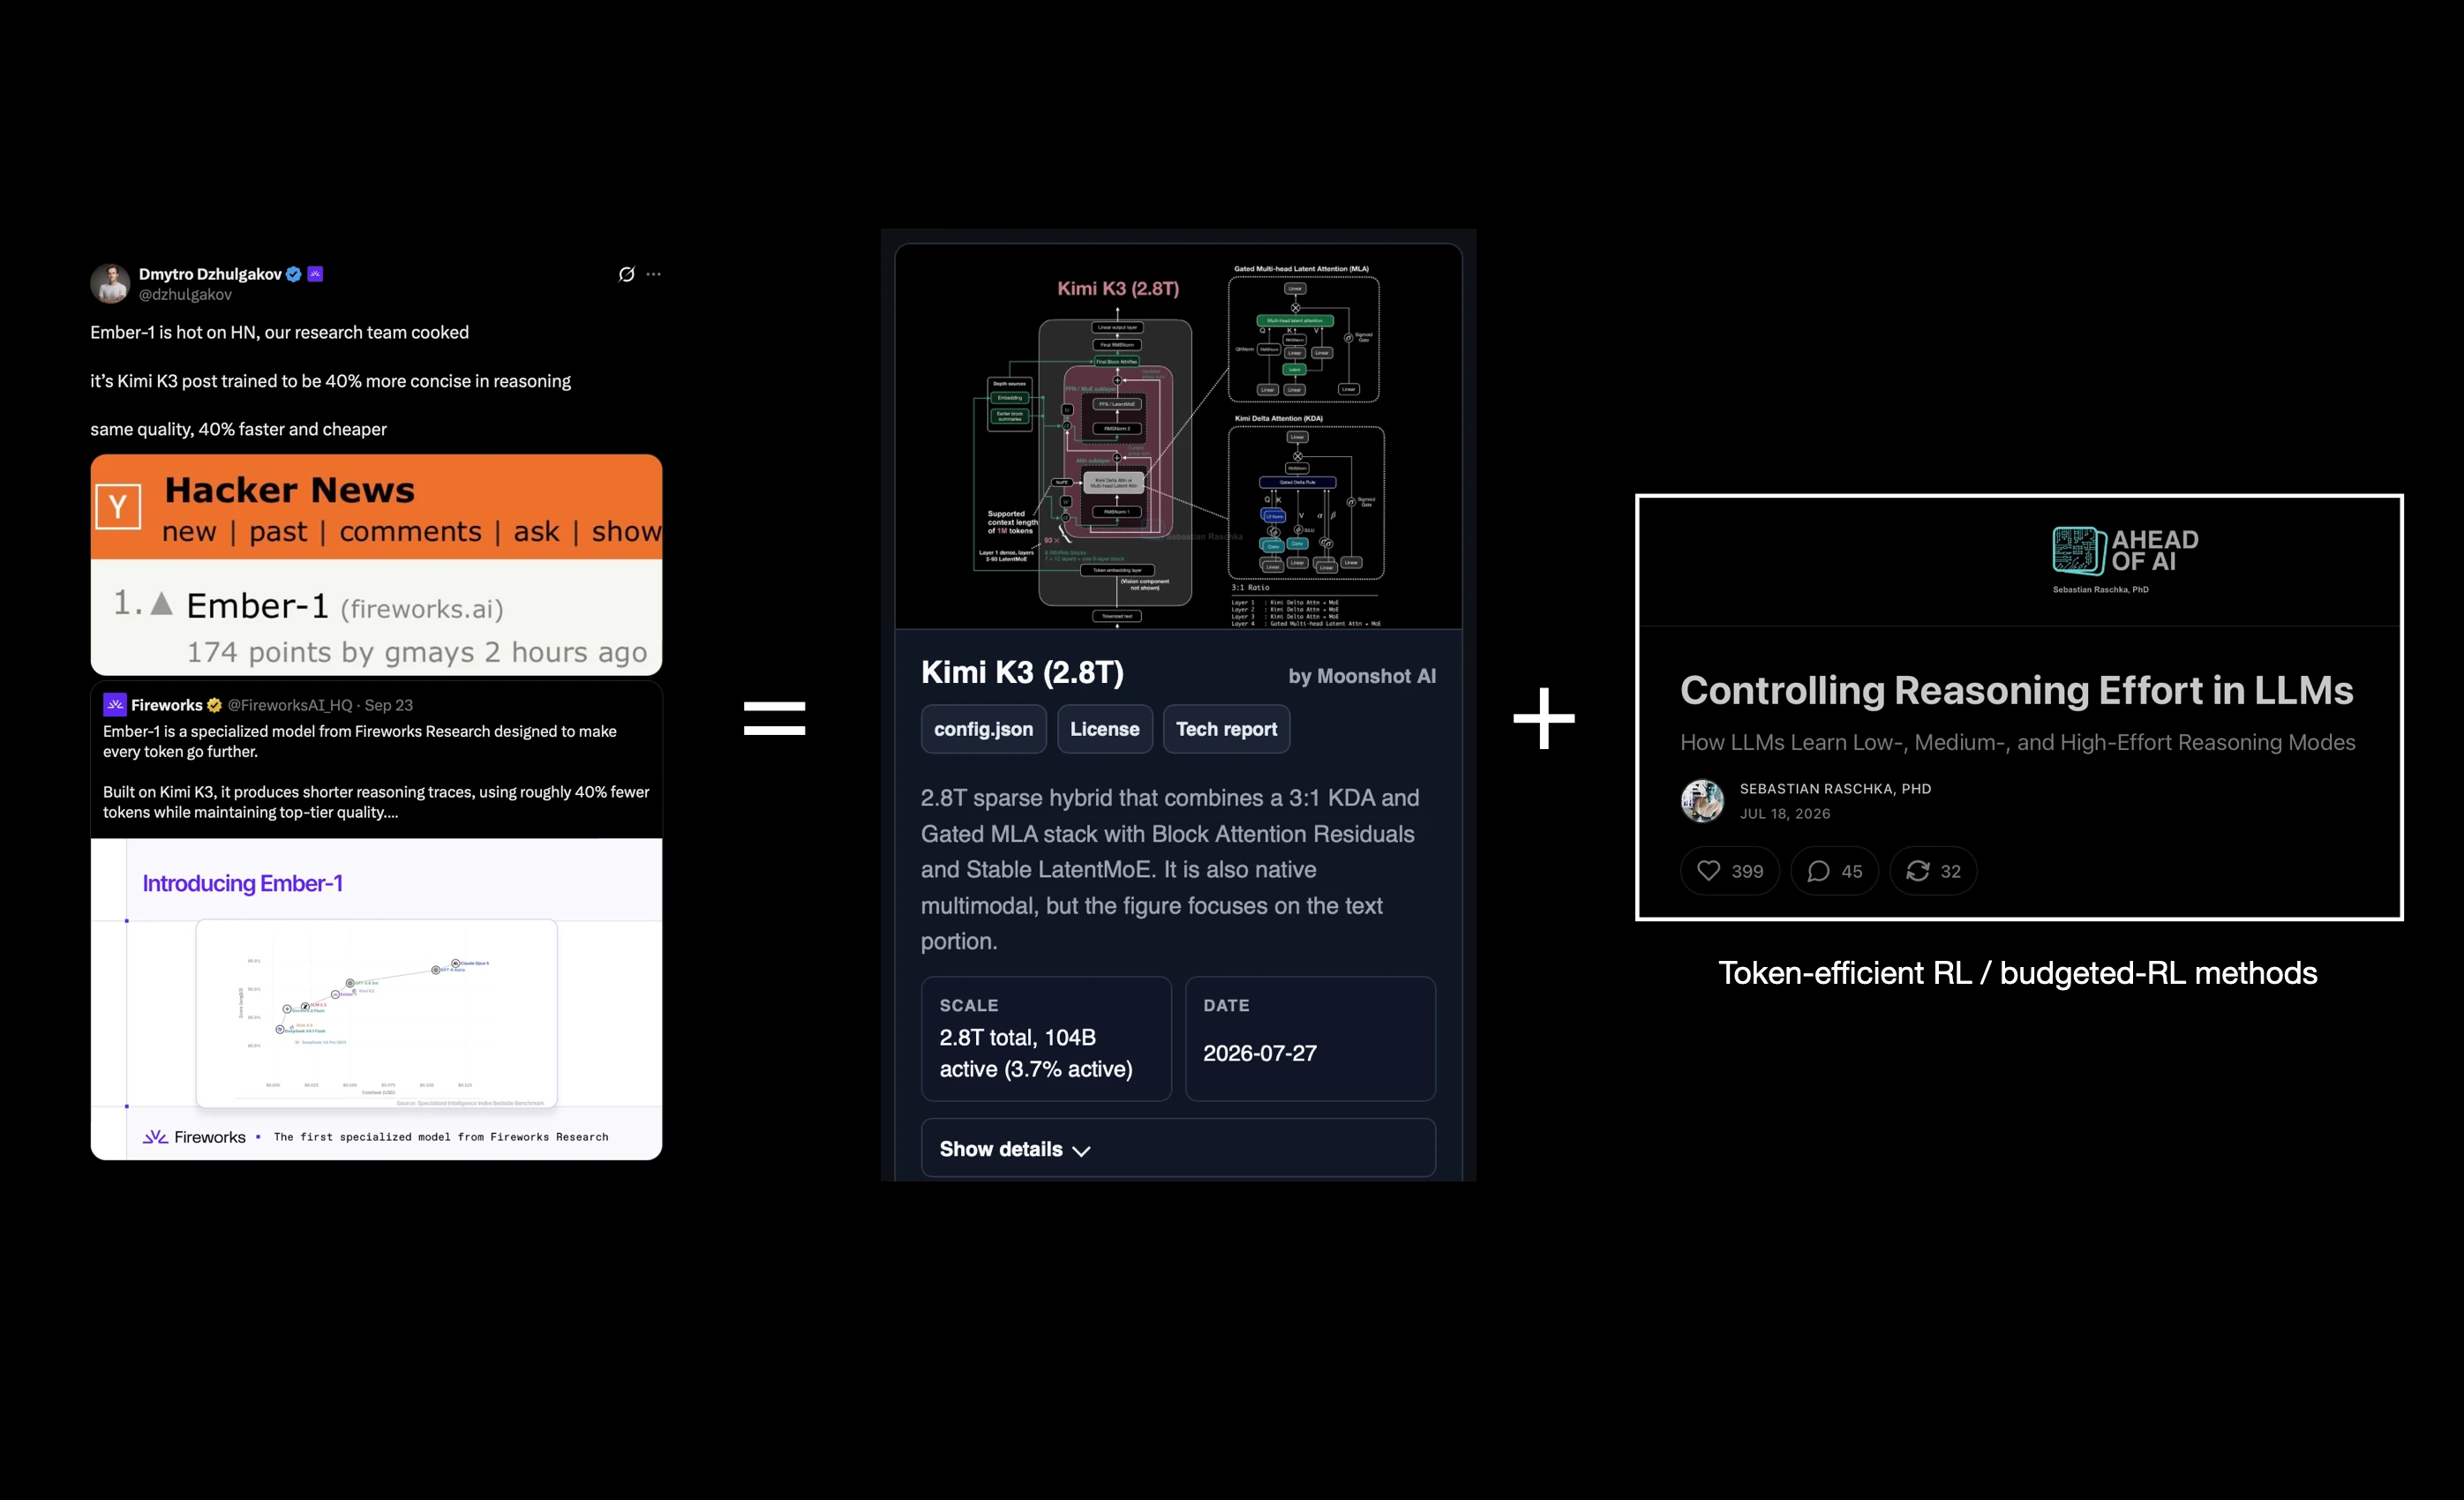 Focusing on Post-Training
Why I'd invest in post-training existing open-weight LLMs, with Fireworks' Ember-1 as an example of more token-efficient reasoning.